TL;DR
We help performance teams turn scattered creative testing into a weekly evidence system. This article shows how to classify test levels, stop or continue live ads, use competitor evidence without imitation, score the backlog, allocate the portfolio, and preserve decisions for the next cycle.
Creative quality is a measurable performance lever, not a nice-to-have. In Meta’s analysis of 15 split tests, vertical Reels ads with audio and safe-zone messaging had a 34.5% lower cost per result than image ads on Reels, according to Meta research.
A paid social creative testing framework should rank experiments by evidence and learning value, not team preference or production convenience. Each weekly decision combines current performance, fatigue and stop signals, relevant competitor patterns, and unresolved backlog questions. The output is a short, owned sequence of hypotheses with success criteria, kill criteria, and next actions.
Below, we show how to turn that sequence into a weekly operating system your paid media, creative, and analytics teams can actually run.
What Is a Paid Social Creative Testing Framework?
A testing framework is not a larger swipe file or a faster way to produce variants. We use it as a decision system that reconciles four inputs every week: live-test signals, first-party performance, competitor observations, and the unresolved questions in the backlog.
The objective is simple: make the next test more informed than the previous one. That requires separating strategic questions from production tweaks, recording what conditions shaped a result, and giving every test a clear next action.
| Test Level | Decision It Answers | Test Before | Useful Output |
|---|---|---|---|
| Concept | Is this core creative idea worth pursuing? | All lower-level work | Keep, replace, or expand the idea |
| Angle | Which message or customer problem has promise? | Hook and format work | A validated message territory |
| Hook | What earns initial attention? | Executional polish | A stronger opening direction |
| Format | How should the idea appear in-feed? | Element tweaks | A format recommendation |
| Execution | Which treatment best delivers the same idea? | Element tests | A sharper production brief |
| Element | Which small component improves an established asset? | Nothing lower | Incremental optimization |
We connect this hierarchy to creative intelligence software so teams can identify whether weak results point to an exhausted concept, a poor execution, or simply an untested question.
Which Creative Test Should You Run First?
Start at the highest unresolved decision. If a team has not established which customer problem, promise, or story can earn attention, changing captions, crops, colors, or calls to action creates activity without usable learning.
Test Concepts and Angles Before Elements
Concept tests compare different strategic ideas. Angle tests compare messages within a promising idea. Both are more valuable than element work when the team still lacks a clear explanation for why an ad should resonate.
For example, a team may test whether a customer pain point, a proof-led story, or a product demonstration is the stronger concept. Once one direction shows promise, it can test specific angles before moving into hooks and formats.
Isolate the Variable That Matters
A clean test changes one meaningful variable while keeping the audience, offer, measurement approach, and other creative conditions as comparable as possible. TikTok’s testing guidance recommends parallel ad groups, one isolated variable, and at least 14 days of testing for its platform setup.
That guidance is a useful reference point, not a universal rule. We set duration and spend requirements around each account’s conversion volume, normal volatility, and confidence needed for the next decision.
Treat Hooks, Formats, and Executions as Follow-Up Questions
Once a concept or angle earns further investment, test what makes it work in-feed. A hook can change the first visual, opening claim, or proof device. A format can change how the story is delivered. An execution can change pacing, talent, visual treatment, or product demonstration.
We recommend tagging each result at the creative-attribute level. That makes angle tracking more useful than a flat list of winning ads, because the team can see which messages survive across different executions.
What Should Stop, Continue, or Be Retested?
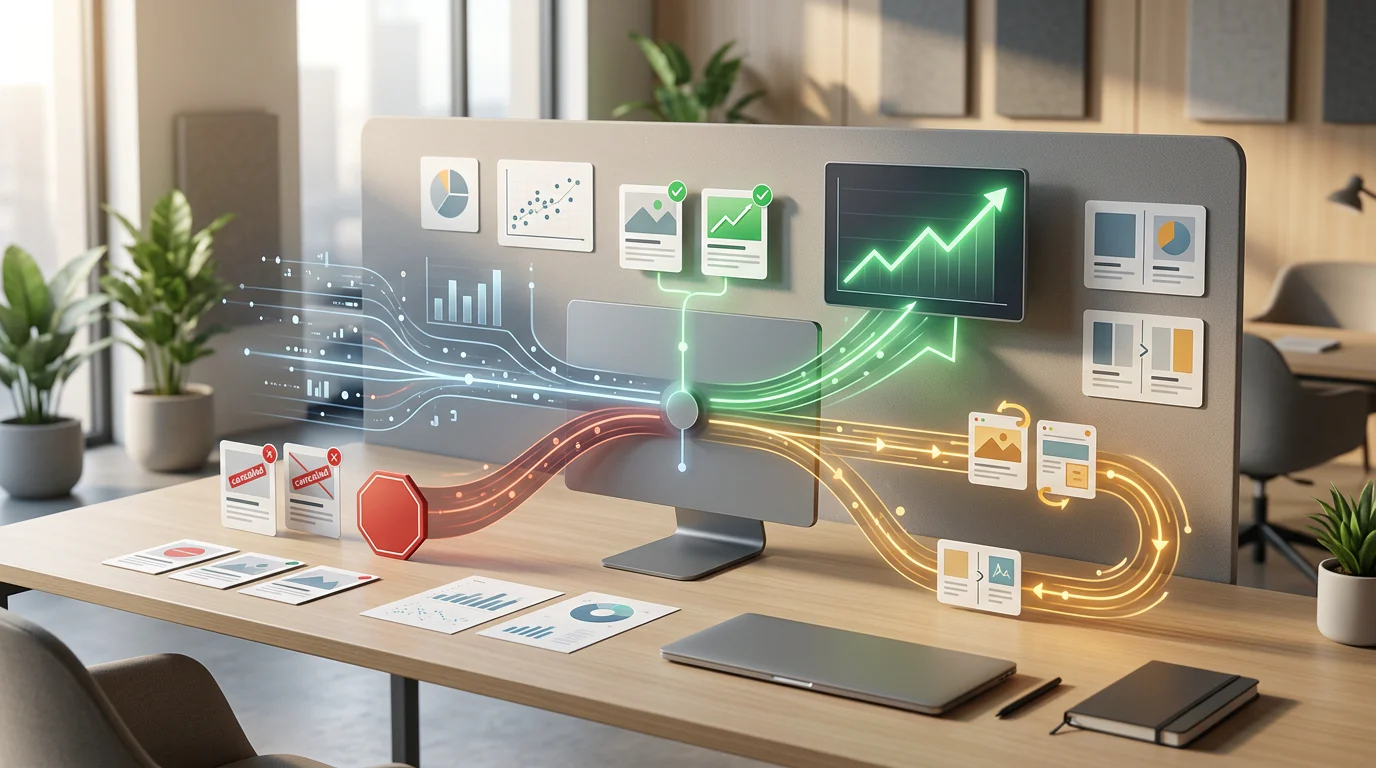
Weak ads rarely announce their failure with one clean signal. Frequency, reach, spend, attention, click behavior, conversion quality, and auction conditions can all move at once. We read them together before deciding whether to stop, continue, or retest.
TikTok’s 2025 research with 8,000 heavy users across six markets found that 51% preferred brands with a variety of content, reinforcing why refresh decisions should be based on a pattern of fatigue signals rather than a single dashboard number. Fatigue research
Read the Signals Together
Continue a test when it is still gathering comparable evidence and the original hypothesis remains testable. Stop it when the pre-agreed failure condition has been met after sufficient delivery. Retest when a delivery shift, offer change, tracking issue, or audience change makes the result hard to interpret.
We use ad fatigue signals to distinguish a tired creative from a weak proposition. An exhausted execution may deserve a replacement variation, while a repeatedly weak angle usually needs a different strategic question.
Record the Decision Before Moving On
Every weekly review should produce a short explanation: what happened, what evidence supports the interpretation, what limits confidence, and what action follows. This prevents a team from relaunching the same idea weeks later because the original result was never made searchable.
The purpose is not to automate judgment away. It is to remove avoidable arguments after spend has already been committed and make the next decision easier to explain.
How Should Competitor Evidence Shape New Tests?
Competitor research is useful when it expands the hypothesis pool. It becomes harmful when it turns into imitation or gets mistaken for performance proof. We treat public ad evidence as a signal of what is being attempted, not evidence that a specific creative is converting.
A useful weekly evidence sheet captures recurring angles, proof types, formats, offer framing, and refresh patterns. It does not copy scripts, imagery, claims, or brand identity. The resulting question should always be original: “Could this proof type reduce this audience’s objection for us?”
Filter for Repetition and Relevance
One ad can reflect a temporary launch, a seasonal offer, or an unproven experiment. Repeated patterns across relevant advertisers deserve more attention, especially when they align with first-party comments, objections, or performance gaps.
TikTok’s public Commercial Content Library covers ads targeted to the EEA, Switzerland, and UK. It can take up to 24 hours for an ad to appear, and ads with at least one view remain available for one year after their last view. Library details
Convert Observation into Validation
The best use of competitor evidence is a testable hypothesis, not a creative brief. We compare the observation against our own audience, offer, comments, and historical creative results before it enters the backlog.
That keeps own versus competitor signals in the right order: outside evidence generates questions, while first-party evidence decides whether those questions deserve spend.
How Do You Rank and Launch a Weekly Test Backlog?
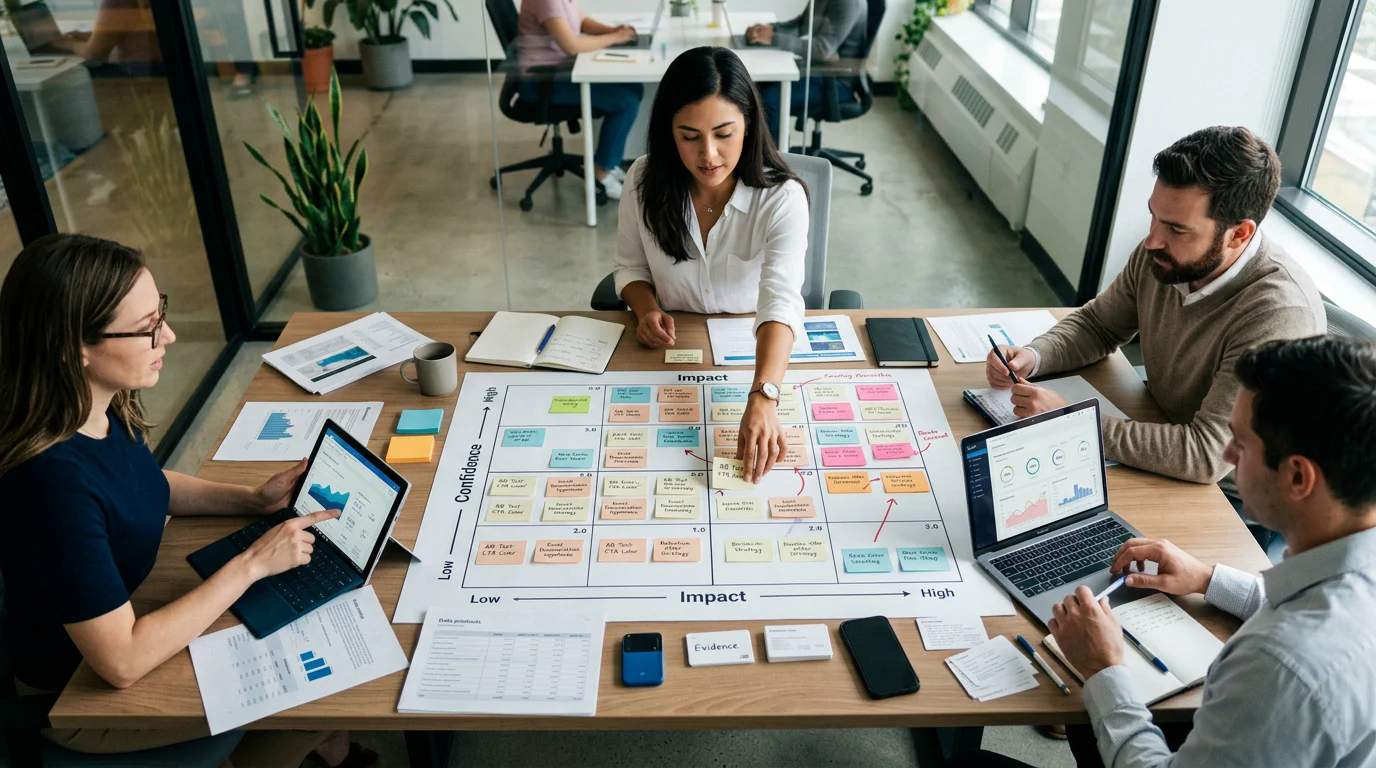
A useful backlog ranks decisions, not assets. “Make three more videos” is production work. “Test whether proof-first hooks outperform pain-first hooks for cold audiences” is an experiment. We only prioritize the latter.
Score Hypotheses with Transparent Weights
We use a 1 to 5 scale for every criterion. Impact and learning value count twice because the best tests can improve both this week’s results and future creative decisions.
| Criterion | What The Team Assesses | Weight |
|---|---|---|
| Impact | Potential business upside if the hypothesis is right | 2 |
| Confidence | Strength of the causal rationale | 1 |
| Evidence Quality | Reliability and relevance of supporting signals | 1 |
| Effort | Production, approval, and launch burden | Minus 1 |
| Risk | Brand, compliance, measurement, or opportunity cost | Minus 1 |
| Learning Value | Number of future decisions the result can unlock | 2 |
Use this formula: Priority Score = 2(Impact) + Confidence + Evidence Quality + 2(Learning Value) - Effort - Risk. The point is not mathematical theater. It is a visible way to explain why one question deserves the next production slot.
Use a Standard Test Card
A test card makes the proposal operational before anyone produces assets or changes budget.
| Field | What To Record |
|---|---|
| Hypothesis | Causal prediction and rationale |
| Variable | The sole intentional change |
| Control | What remains comparable |
| Audience | Eligible audience and exclusions |
| Metric | Primary outcome and diagnostic metrics |
| Success Criterion | Result required to advance |
| Kill Criterion | Result that ends the test |
| Owner | Decision-maker and operator |
| Follow-Up | Scale, iterate, replace, or archive |
We use test prioritization to keep these cards in one ranked system, rather than splitting rationale across creative briefs, campaign notes, and meeting recordings.
Fund Four Different Jobs
Do not let all available production and media capacity flow to easy variants of yesterday’s winner. Every portfolio needs room for proven work, measured iteration, strategic exploration, and fatigue replacement.
| Portfolio Lane | Purpose | Funding Rule |
|---|---|---|
| Exploitation | Confirm and extend proven winners | Give the largest share when results are stable |
| Iteration | Improve a validated concept or angle | Protect capacity for controlled follow-ups |
| Exploration | Answer new strategic questions | Reserve visible capacity for new learning |
| Replacement | Refresh assets facing fatigue or expiry | Fund when active creative needs renewal |
We size each lane to the account’s real budget and production capacity instead of imposing a universal percentage. That keeps the portfolio honest when a team is scaling quickly, managing low conversion volume, or rebuilding after fatigue.
Our test stop rules keep the ranked backlog connected to active decisions, so the team does not add new work while unresolved weak tests continue consuming attention and spend.
Run a Weekly Decision Cycle
Run the same sequence every week: review active evidence, classify stop and continue decisions, add new hypotheses, score the backlog, approve the slate, build and QA assets, launch, then log the learning. The meeting should end with fewer open questions, not a longer unranked list.
A four to eight week roadmap keeps the weekly process connected to a bigger learning agenda.
| Timeframe | Primary Focus | Expected Output |
|---|---|---|
| Week 1 | Establish baselines and triage active tests | Clear stop, continue, and retest decisions |
| Weeks 2 To 3 | Explore concepts and angles | Promising strategic directions |
| Weeks 4 To 5 | Validate hooks, formats, and executions | Sharper production guidance |
| Weeks 6 To 8 | Confirm, scale, replace, and synthesize | Reusable learning and next backlog |
Build the System with Deepsolv
At Deepsolv, we built our platform for the moment after a team has collected more signals than it can reasonably sort through. We bring together creative performance, competitor observations, comments, and test history so the next decision starts with evidence, not another dashboard debate. Our workflow helps teams identify fatigue risk, trace results back to angles and executions, and turn unresolved questions into owned test cards. That means the paid media lead, creative strategist, and analyst can work from the same ranked plan, with clear reasons to stop, iterate, explore, or scale. We also make the result easier to preserve, so a hard-won lesson does not vanish when a campaign ends or a teammate changes roles. If your weekly creative meeting still produces a longer list than it resolves, we can help you turn it into an operating system. Deepsolv
FAQs on Paid Social Creative Testing Framework
How Do Teams Prioritize Ad Creative Tests?
Rank backlog hypotheses by impact, evidence quality, learning value, effort, and risk after reviewing live results. Launch only work that resolves the next meaningful decision.
When Should a Team Stop Testing an Ad?
Stop an ad after comparable delivery meets its pre-agreed failure condition, or changing conditions invalidate the read. Record why before reallocating budget, production capacity, or assets.
How Should Competitor Evidence Affect the Backlog?
Use public ad evidence to identify recurring messages, formats, or proof styles, then create original hypotheses. Validate each with your audience, measurement, and creative standards.
What Belongs in a Paid Social Test Card?
A test card records the hypothesis, variable, control, audience, metric, success criterion, kill criterion, owner, and next action, making each result reusable after testing ends.