Own Ad Performance Versus Competitor Ad Signals
Compare first-party Meta performance with public competitor signals, join them through tags and events, and rank smarter creative tests.
Creative intelligence needs more than a larger swipe file. A 2019 field study comparing 15 U.S. advertising experiments found that common observational approaches often failed to reproduce randomized results.
Own ad performance versus competitor ad signals answer different creative questions. Your account data shows which tagged assets were credited with defined business outcomes under your measurement settings; public market data shows messages that are visible, persistent, or changing. Join them with a shared taxonomy and customer evidence to rank hypotheses, not to declare a competitor’s creative proven.
In this guide, we show how we separate those evidence types, connect creative concepts to conversion outcomes, and turn the combined signal into a practical test queue.
What Own Ad Performance Versus Competitor Ad Signals Can Tell You
We treat first-party performance and public market research as complementary inputs, not substitutes. Our account data can establish what delivered, what was clicked, and what was credited with a defined conversion event. Public observations can show which ideas are present in the market. Neither alone explains the full reason an angle will or will not work for your brand.
| First-Party Creative Performance Data | Public Competitor Creative Signals |
|---|---|
| Questions Answered: Which tagged assets, angles, formats, and audiences received delivery and were credited with our business outcomes? | Questions Answered: Which messages, offers, proof types, formats, and creative patterns are currently visible, persistent, or changing in the market? |
| Evidence Strength: Strong for reported account delivery and attributed outcomes. Stronger when validated with a suitable experiment. | Evidence Strength: Descriptive market evidence. It shows observable activity, not verified financial outcomes. |
| Blind Spots: Attribution settings, incomplete event capture, modeled reporting, and confounding can affect interpretation. | Blind Spots: Public activity does not reveal commercial-ad spend, targeting, attribution, conversion volume, margin, or profitability. |
| Decisions Supported: Iterate, pause, scale, or retest our creative concepts against verified account benchmarks. | Decisions Supported: Find patterns, identify whitespace, and form original creative hypotheses worth testing. |
A low cost per click is an engagement signal, not a conversion verdict. Likewise, a persistent public ad may be worth studying, but its visibility does not confirm that it generated profitable acquisition. We use a creative intelligence system to keep the question attached to the right evidence source.
What Public Ad Signals Reveal, and What They Cannot Prove
Public ad data is useful when we label it honestly. For commercial ads, Meta's Ad Library lets people search currently active ads across Meta products. That is valuable for tracking message changes and recurring formats, but it is not a window into an advertiser’s business results.
Start with the Strongest Evidence
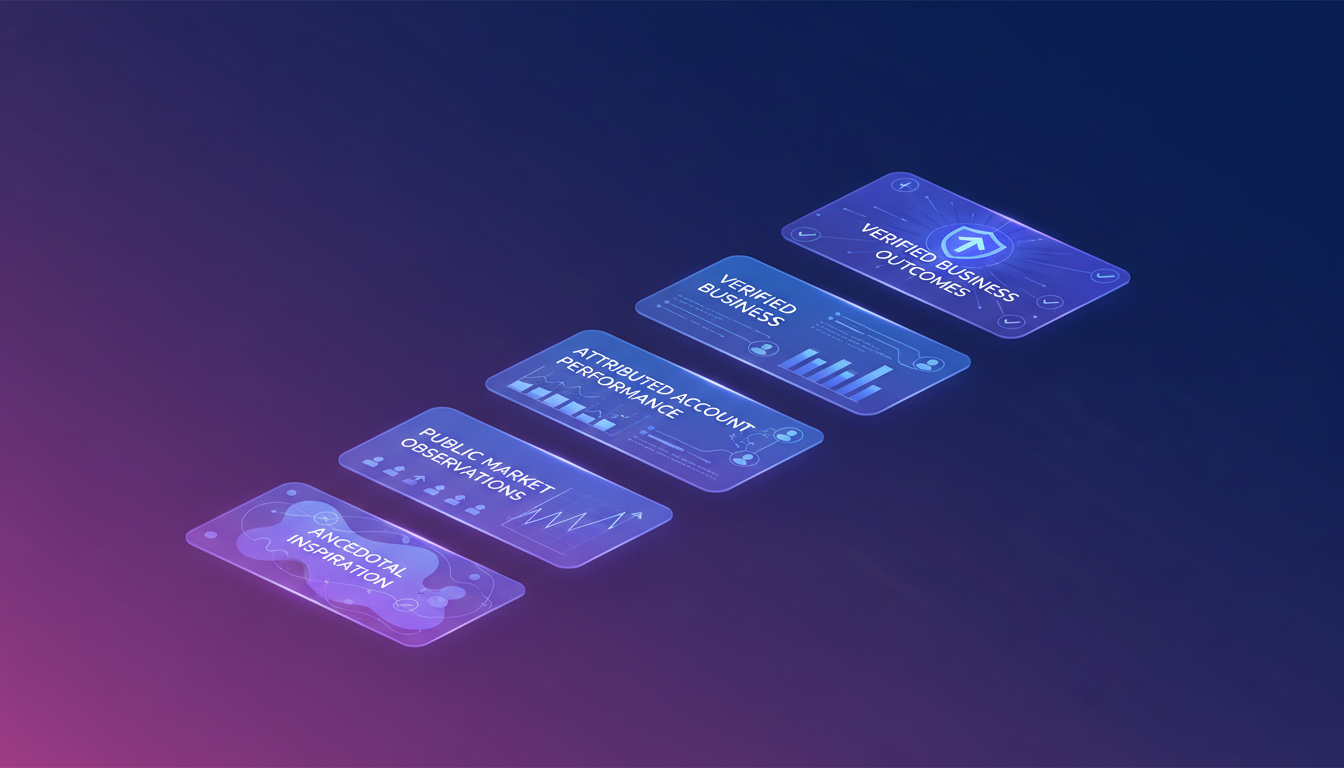
Our signal hierarchy prevents market activity from being mistaken for proof.
- Verified Business Outcome: A defined purchase, qualified lead, or other business event linked to our account’s measurement setup.
- Attributed Account Performance: Platform and analytics reporting that credits an asset or campaign under a stated attribution model.
- Public Market Observation: A timestamped creative, offer, or format that is visible in a public source.
- Anecdotal Inspiration: A single ad, comment, or opinion that may generate an idea but cannot rank above outcome evidence.
Public-platform metrics can also vary by source. For example, TikTok's Top Ads documentation describes filters and relative performance views, including sorting by reach, CTR, and CVR. Those measures can help reveal how creative is presented on that platform, but they still do not become your account’s conversion proof.
Treat Persistence as a Prompt, Not a Verdict
A message that remains visible may indicate that a brand continues to run it. It may also reflect retargeting, a long campaign flight, creative operations, a niche audience, or a result that only makes sense for that advertiser’s economics. We do not copy persistent ads. We ask what customer problem, promise, proof, or format pattern is worth testing in our own voice.
Record How the Signal Was Captured
“Live” can mean a native public-library search, a scheduled collection, or a manual screenshot. Those are different levels of freshness and coverage. We record the source, observed date, advertiser identity, platform, market, format, and collection method so teams can see what they know and what they do not know. Our automated competitor tracking process is designed to preserve that context instead of creating an unsearchable archive.
How to Join Ad-Library Data with Meta Results
The practical answer is not to join a competitor’s public ad to private conversion data. We join our own concepts, asset records, URLs, and conversion events, then compare those verified results with the public patterns we have documented. That distinction is what lets a multi-account team reduce spreadsheets without creating false certainty.
Create a Shared Creative Taxonomy
We give every asset a consistent set of labels: hook, angle, offer, proof type, format, audience, funnel stage, product, landing page, market, and asset ID. Each label needs a short definition. “Problem aware” and “pain point” cannot be separate labels one week and treated as identical the next.
This structure lets us compare a product demonstration with a testimonial without pretending they are the same creative idea. It also lets us aggregate variants of an angle while retaining the asset-level detail needed to diagnose why one version converted and another only earned clicks.
Connect the Records in Five Steps
Google's tagging guide explains that utm_content can distinguish creatives, while consistent campaign parameters preserve usable reporting. We use that principle across the following workflow.
-
Assign Stable IDs: Give each creative concept and asset an ID that survives campaign rebuilds, edits, and exports.
-
Name Ads Consistently: Include market, funnel stage, angle, hook, format, asset ID, and iteration in campaign, ad set, or ad names.
-
Pass Consistent URLs: Use source, medium, campaign, and content parameters that map back to the concept and asset record.
-
Define Outcome Events: Specify the downstream business event before reading results, whether that is a purchase, qualified lead, subscription, or another meaningful action.
-
Capture Public Observations: Save the public creative with its source link, date, market, message labels, and any visible landing-page pattern.
Our angle tracking framework helps teams make these tags useful for decisions rather than just administrative fields.
Add Customer Evidence Before Explaining Performance
A creative can attract attention because it names a real problem, then fail to convert because its promise feels vague, its proof is weak, or the offer creates friction. We connect comments, DMs, sales notes, reviews, and support themes to the same taxonomy. This gives the media team a reason for a performance pattern, not just a metric.
Meta says its Conversions API can connect website, app, offline, and messaging events to measurement across the customer journey. That makes event quality important, but it does not eliminate the need to inspect the customer’s actual objections. That workflow turns those objections into testable creative briefs.
How to Rank Creative Tests Without Mistaking Cheap Clicks for Evidence
We rank concepts by the quality of evidence behind them, not by the loudest metric in a dashboard. A good scorecard makes the team state its account-specific benchmark, comparison period, and confidence level before it recommends another test.
We use the same feedback-to-test workflow to preserve the customer language that explains why a creative earned attention but did not earn a downstream result.
Build an Angle Scorecard
| Scorecard Field | What We Use It For |
|---|---|
| Angle And Supporting Assets | Group related variants while preserving asset-level performance. |
| Business Outcome | Evaluate the defined event, not clicks alone. |
| Spend, Conversions, CPA, CVR, And ROAS | Compare against verified account benchmarks for the same market, objective, funnel stage, and date range. |
| Customer Evidence | Record the relevant objection, motivation, or expectation from customer conversations. |
| Public Market Pattern | Log observable repetition, change, or whitespace without labeling it proven performance. |
| Confidence Label | Mark the test as high, medium, or exploratory based on the evidence available. |
Turn the Score into a Test Hypothesis
A high-confidence concept has enough verified account outcome evidence and customer evidence to support a focused iteration. A medium-confidence concept has a directional result with meaningful uncertainty. An exploratory concept has a useful market or customer signal but no account conversion evidence yet.
For example, if a problem-first hook is becoming more visible in the market, our own version earns qualified leads at or above our account benchmark, and customer conversations repeatedly describe the same frustration, we may test a stronger proof format against the existing offer. We do not conclude that public visibility caused the result. We write a narrower hypothesis and define the event that would validate it.
Our test-prioritization system gives those hypotheses an owner, an evidence trail, and a clear reason to be tested before less-supported concepts.
Select Tools by the Evidence Needed
| Workflow Need | Capability Required | Evidence Standard |
|---|---|---|
| Verify Our Creative Performance | Account-level delivery and conversion-event reporting | Asset IDs, conversion definitions, attribution settings, and account benchmarks |
| Find Market Activity | Public-ad search, filters, timestamps, and source links | Observable activity only |
| Reduce Spreadsheet Work | Scheduled capture, deduplication, shared taxonomy, and change history | Documented refresh cadence and collection limits |
| Explain Conversion Gaps | Customer-feedback collection and objection tagging | Traceable evidence from real conversations |
| Prioritize Tests | Joined scorecard, confidence labels, owners, and test records | A preserved evidence trail, including failed tests |
Attribution assigns credit across touchpoints according to the attribution settings in use. That is why we compare like with like and retain the attribution window, audience, market, landing page, and conversion definition alongside every recommendation.
Avoid the Common Analytical Errors
We avoid declaring an angle “winning” because it has a low CPC, runs for a long time, or looks similar to a public trend. We also avoid comparing two assets that used different audiences, objectives, markets, or landing pages as though the creative were the only variable.
Modeled conversion reporting can be useful, but modeled conversion data is still an estimate when direct observation is unavailable. We use it as part of the record, then choose the appropriate confidence label and test design.
Build Your Creative Intelligence Workflow with Deepsolv
At Deepsolv, we help paid-social teams use our hook stopping framework as they move from scattered screenshots and exports to a decision system that remembers what happened. We bring your creative taxonomy, asset history, account performance, public market observations, and customer feedback into one view, so the next test begins with evidence instead of recency or opinion.
Our role is not to pronounce a visible ad successful. We help your team document the signal, connect it to the outcome you can verify, and preserve the result for the next planning cycle. That makes it easier to compare multiple accounts, hand off context between media and creative teams, and explain why a test deserves budget. We designed our process to keep source dates, evidence limits, and learning records visible whenever a team makes a creative decision. Start with Deepsolv
FAQs on Own Ad Performance Versus Competitor Ad Signals
These answers clarify how we use public market research without confusing it for verified creative performance. They also explain the minimum structure needed to turn activity into an accountable test decision.
Does Creative Intelligence Use Competitor Data?
Yes. We use public competitor data to identify observable messages and market changes, then pair it with account outcomes and customer feedback before prioritizing original tests.
How Do I Track Which Meta Ad Angles Drive Conversions?
Tag every asset’s angle, hook, format, offer, and ID. Connect consistent URLs and conversion events, then compare downstream results across equivalent audiences, objectives, markets, and dates.
How Do I Combine Public Ad-Library Data with Meta Results?
Treat public records as timestamped market observations. Join internal labels, ad names, asset IDs, URLs, and conversion events, never assigning public ads your private outcomes.
Do Competitor Ad-Tracking Tools Pull Live Data or Use Manual Capture?
Confirm the source, collection method, refresh cadence, timestamps, coverage, and deletion handling. Activity may be captured manually, on a schedule, or through a public source.
Why Does Competitor Ad Research Break Down at Scale?
Research fails when screenshots lack labels, dates, ownership, and links to outcomes. A shared taxonomy and confidence-ranked test queue turn collection into accountable weekly decisions.