TL;DR
We believe a Meta creative analysis tool should connect each ad to reliable performance data, comparable creative attributes, and a documented next test. This guide separates reporting, attribution, fatigue alerts, and causal evidence, then shows how to compare setup, signals, actions, and team fit. At Deepsolv, we use that standard to turn market, customer, and account signals into an inspectable weekly test plan.
Which Meta Creative Analysis Tool Fits Your Growth Team?
Meta reports that Reels campaigns using suitable 9:16 video with audio and safe-zone messaging achieved a 34.5% lower cost per result than image ads in its meta-analysis of 15 split tests. That is useful evidence for a creative decision, but it does not make every vertical video a winner in every account.
A Meta creative analysis tool fits a growth team when it places the ad beside reliable performance data, groups comparable creatives, identifies usable element-level patterns, and preserves the finding for the next test. Reporting summarizes outcomes, while analysis explains patterns. Neither alone proves causation.
We compare the decisions each tool category can support, the evidence behind its recommendations, and the setup questions that matter before a team commits. The aim is not another dashboard, it is a better weekly test queue.
What Decision Should a Growth Team Buy a Tool to Support?
The most useful purchase question is not, “Which platform has the most AI features?” It is, “Which decision are we currently unable to make?” A team that cannot see creative-level CPA has a reporting problem. A team that sees the metrics but cannot isolate whether a hook, offer, or format is associated with the result has an analysis problem.
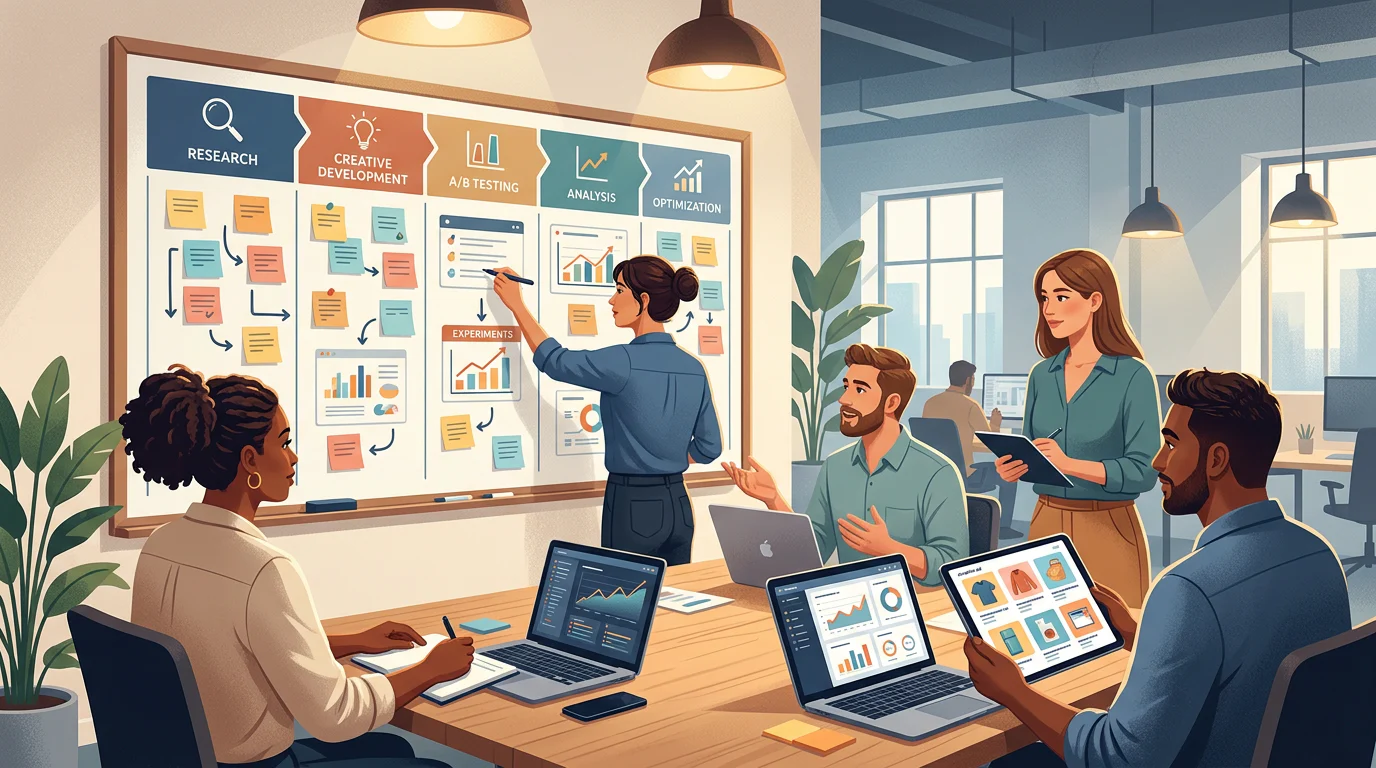
A team that has plenty of observations but no durable answer to “what should we test next?” needs a decision system. That system should retain the hypothesis, variable, success metric, and outcome, much like the disciplined workflow behind a fair test control.
| Job | Question It Answers | Data It Needs | What It Can Safely Claim | Useful Output |
|---|---|---|---|---|
| Ad Reporting | What happened? | Platform metrics and date ranges | Descriptive performance | Report or dashboard |
| Creative Analysis | Which patterns are associated with outcomes? | Ads, taxonomy, creative-level metrics | Observed pattern | Diagnostic finding |
| Attribution | Which touchpoints receive credit? | Defined events, windows, and model | Model-based credit assignment | Attributed revenue or conversions |
| Fatigue Monitoring | Which assets need investigation? | Time series, delivery context, baselines | Risk signal, not diagnosis | Review alert |
| Test Planning | What should we make, change, pause, or scale next? | Analysis, customer evidence, research, prior tests | Prioritized hypothesis | Brief with decision rule |
Public ad research belongs in that workflow, but only as market context. Meta’s Ad Library can show observable creative and delivery information, while your own authorized account data is what supports decisions about your spend.
How Does a Meta Creative Analysis Tool Differ from Reporting?
Reporting is essential, but it is not automatically analysis. A report may sort ads by spend, ROAS, CPA, CTR, or placement. Analysis has to make the ads comparable, identify the creative variables under review, and show why an observed pattern deserves a test.
We use a simple checklist before treating a tool output as creative analysis. It keeps teams from promoting an attractive chart into a recommendation it cannot support.
- Ad Visibility: Can the team see the actual asset beside the metric?
- Comparable Groups: Can similar ads be grouped independently of campaign naming?
- Tag Auditability: Can a strategist inspect and correct the labels applied to hooks, visuals, copy, audio, or offers?
- Metric Context: Does the view state the attribution source, time window, audience, placement, and objective?
- Actionability: Does the finding become a specific variable to test or a decision to pause?
- Memory: Can the next planner see what was tested, what happened, and why?
The difference matters because a strong creative team needs more than a weekly winner list. It needs a way to track creative angles across iterations without confusing a renamed variation for a new learning.
When we move from analysis to proof, we narrow the claim. Meta’s testing guidance recommends keeping other variables constant and allowing at least 14 days in its example, which is why a clean testing approach matters more than a confident-looking score.
What Capabilities Matter Most When Comparing Tools?
A comparison becomes useful when each row is judged by the same decision standard. We look for whether a system can normalize account data, understand the ad itself, expose the evidence behind a recommendation, and preserve a result after the campaign ends.
Account Connections and Normalization
Ask which networks, accounts, campaigns, and ad-level metrics the platform can actually access. Then ask how it handles duplicated assets, renamed campaigns, multiple countries, placements, changing attribution windows, and historical backfill.
A multi-account view is only useful if the definitions remain clear. We recommend confirming whether a creative is grouped by asset, ad ID, variant family, or an automated similarity model before trusting a blended result.
Tagging Depth and Creative-Level Metrics
The useful distinction is not whether a product says it uses AI. It is whether a team can inspect the attributes that produced a pattern, including hook, offer, on-screen text, voiceover, visual format, scene, creator, product proof, and call to action.
A 2024 field study analyzed 2,308 online video ads using human and machine coding, which illustrates why creative attributes need a defined methodology instead of vague labels such as “high quality.” We use tags to form hypotheses, not to turn correlation into certainty.
External Signals and Test Recommendations
Most tools can organize owned ad data. Fewer can connect observable market activity, permitted reviews or comments, and historical test outcomes to the next brief. That gap matters when the team’s bottleneck is deciding what to make, not merely sorting what already ran.
At Deepsolv, we connect those sources into a signal-to-copy workflow: identify an objection or opportunity, link it to account evidence, define one creative variable, and record the result for the next planning cycle.
| Tool Category | Primary Decision | Tagging Depth | External Signals | Recommended Action | Pricing Approach | Setup Effort | Best Fit |
|---|---|---|---|---|---|---|---|
| Native Meta Reporting | What happened in the account? | Limited to platform views | No | Manual interpretation | Included with account access | Low | Lean teams needing visibility |
| Reporting-First Platform | Which assets performed best? | Asset or campaign grouping | Limited | Visual report or review list | Published tier or quote | Low to medium | Teams sharing frequent reports |
| Element-Analysis Platform | Which creative attributes align with results? | Structured creative attributes | Usually limited | Pattern-led hypothesis | Published tier or quote | Medium | Teams with repeatable testing volume |
| Automation-Centric Platform | What should change in active media? | Varies by setup | Usually limited | Automated optimization or alert | Quote or in-app pricing | Medium | Media-buying workflows |
| Enterprise Benchmarking Platform | How does creative quality compare at scale? | Broad creative data model | Benchmark data | Governance or quality recommendation | Custom quote | High | Large, governed organizations |
| Generation-First Platform | What new assets can we produce? | Prompt or asset metadata | Depends on supplied inputs | New draft or variant | Credit or subscription model | Low to medium | Production-constrained teams |
| Deepsolv | What should we test, improve, or stop next? | Creative, message, and evidence context | Customer signals, observable market activity, test memory | Ranked weekly test brief | Tailored quote | Scoped onboarding | Meta growth teams and agencies |
How Should Teams Evaluate Fatigue, Attribution, and Causal Evidence?
Creative fatigue is a useful operational term, but it is often used too casually. A falling result may reflect repeated exposure, audience saturation, a changed offer, budget reallocation, placement mix, seasonality, or a measurement change. We treat fatigue as a diagnosis to investigate, not a label to apply after one metric moves.
Fixed Thresholds, Baselines, and Alerts
A fixed threshold can be simple to operate, but it can also create false confidence. A more useful alert compares an asset with its own recent baseline and shows the exact metric, period, audience context, and change that triggered review.
Academic fatigue research supports the broader point that repeated exposure can reduce responsiveness, but it does not create a universal frequency or CPA threshold for every Meta account. We review the creative, delivery conditions, and change history with a defined fatigue framework before recommending a refresh.
Attribution Is Credit, Not Proof
Attribution tells a team how a chosen model assigns conversion credit. It can be highly useful for operations, but it is not the same as incremental impact. Every result should disclose the source, event, attribution window, and model before it informs a creative recommendation.
A 2024 attribution study shows how attribution rules can influence bidding incentives. For our purposes, the practical lesson is clear: do not compare attributed ROAS across tools unless the underlying measurement rules match.
Controlled Tests Support Stronger Claims
We use “associated with” for observations and model outputs. We use “caused” only when a team can explain the test design, the variable changed, the comparison condition, the success measure, and the limitations.
That standard changes what a fatigue tool should do. It should flag an asset for review, recommend a bounded next test, and help preserve the result, rather than silently trigger a claim that a hook or visual element caused a decline. Our test stop policy keeps those decisions explicit.
Which Setup Fits Your Team and Workflow?
Startups, in-house growth teams, mobile acquisition teams, agencies, and enterprises can all use creative analysis. They should not all buy the same workflow. The right system is the one that removes the team’s current decision bottleneck without creating more manual cleanup than it saves.
For a lean Meta team, native reporting plus a clear naming and tagging habit may be enough. For a high-volume team, the value often starts when comparable assets, historical findings, and external signals are too scattered to turn into a weekly decision without a spreadsheet exercise.
Startups and Lean Teams
Choose the simplest route that makes your reporting trustworthy. Confirm the team can see creative-level results, keep a test log, and explain why one result should change next week’s production plan.
In-House Meta Growth Teams
Prioritize a system that connects performance, research, customer language, and previous experiments to a single ranked test queue. We built our workflow for in-house Meta teams that need to turn weekly evidence into concrete briefs.
Mobile Acquisition Teams
Prioritize network coverage, MMP event availability, creative-to-post-install joins, and data latency. Ask for the exact events, currencies, countries, and placement detail available before treating creative findings as comparable.
Agencies and Enterprises
Prioritize account isolation, client permissions, exportable evidence, taxonomy governance, and a clear audit trail. A client-ready report matters, but the deeper value comes when every recommendation still shows its inputs and its limits.
Put Deepsolv to Work
At Deepsolv, we built our workflow for the point where a growth team has plenty of ads and ideas, but not enough confidence in the next brief. We bring permitted customer feedback, observable market activity, authorized performance data, and the outcomes of earlier tests into one decision record. That record makes the evidence visible, identifies the variable worth testing, and keeps the learning after a winner fades or a promising concept fails.
We are not asking teams to treat a model score as proof. Our job is to help them turn incomplete signals into a disciplined test queue, with a hypothesis, an owner, a success metric, and a stop or scale condition. If your weekly review ends with “what should we make next?”, we can make that question concrete, inspectable, and ready for production before media spend and production time are committed to the wrong creative direction. Book a Deepsolv demo
FAQs on Meta Creative Analysis Tool
Which Meta Creative Analysis Tool Is Best for a Growth Team?
The best fit connects ads, reliable performance data, customer evidence, and test history to one explicit decision: what to test, change, pause, or scale next.
Can Reporting Detect Creative Fatigue?
Reporting can reveal a falling result, rising frequency, or reduced delivery efficiency, but it cannot diagnose fatigue alone. We compare baselines, audience conditions, placements, and creative changes first.
Is Attribution Proof That Creative Caused Outcomes?
Not by itself. Attribution assigns credit according to a defined window and model, while causal proof needs an appropriate controlled design, stated measurement rules, and credible comparison conditions.
Can Competitor Ads Prove a Creative Will Convert?
No. Public ads show messages, formats, and observable delivery timing. We use them as research inputs, then test a hypothesis against our authorized performance data and customer evidence.
What Should We Ask Before Buying a Tool?
Ask which accounts, metrics, attribution windows, historical records, creative attributes, and external signals the tool can access. Then ask how it recommends, records, and validates next actions.