TL;DR
At Deepsolv, we use a Meta ad testing framework with stop rules to separate genuine creative losses from thin delivery, measurement problems, and ad-set failures. This guide shows how to set evidence gates, choose one test variable, use guarded automation, make pause or promote decisions, and document each result so the next hook brief improves.
Meta’s analysis of 15 A/B tests found that native vertical Reels creative delivered, on average, a 5% lower cost per result and an 11% higher conversion rate in the studied campaigns. That is useful context, but it is not a reason to treat every new format as a winner. Meta’s test analysis
A Meta ad testing framework with stop rules should stop a single variant only when it has received enough delivery to judge and has crossed a pre-agreed loss limit. Check spend, conversions, CPA or ROAS, CTR, hold rate, frequency, delivery status, and the baseline together. When several variants fail at once, investigate the setup before writing off the creative idea.
We will show how to set clean tests, interpret early signals, define stop decisions, automate safely, and turn every result into a stronger next hook brief.
What Must Be Defined Before a Meta Creative Test Launches?
A test begins before an ad enters review. If the team cannot state what changed, what success means, how much risk is acceptable, and who can act, a disappointing result becomes a debate instead of a decision.
Meta’s learning guidance says an ad set typically stabilizes after roughly 50 optimization events within seven days. That is a delivery context, not a universal stop threshold for a hook. A low-volume account may need a longer window, while a high-spend account can reach a defensible downside decision earlier. Learning guidance
Set up each test in this order:
- Write one hypothesis, such as: “A problem-first hook will improve qualified conversions against the current control.”
- Name one variable, such as the hook, angle, format, offer, or audience.
- Freeze the baseline, including placement mix, attribution setting, date range, CPA or ROAS, and conversion rate.
- Choose one primary business outcome, such as CPA, ROAS, qualified lead rate, or conversion value.
- Choose diagnostic metrics, including CTR, hold rate, landing page view rate, frequency, and delivery status.
- Set a minimum impression level, a minimum conversion level, a spend ceiling, and a review window.
- Check tracking, destination URLs, creative rendering, account status, and policy review before launch.
The practical distinction is simple: the primary outcome determines whether the test creates value, while diagnostics help us explain why. We use prioritize tests to make sure a team is spending its limited testing capacity on hypotheses that can change the next decision.
Which Test Type Is Actually Being Run?
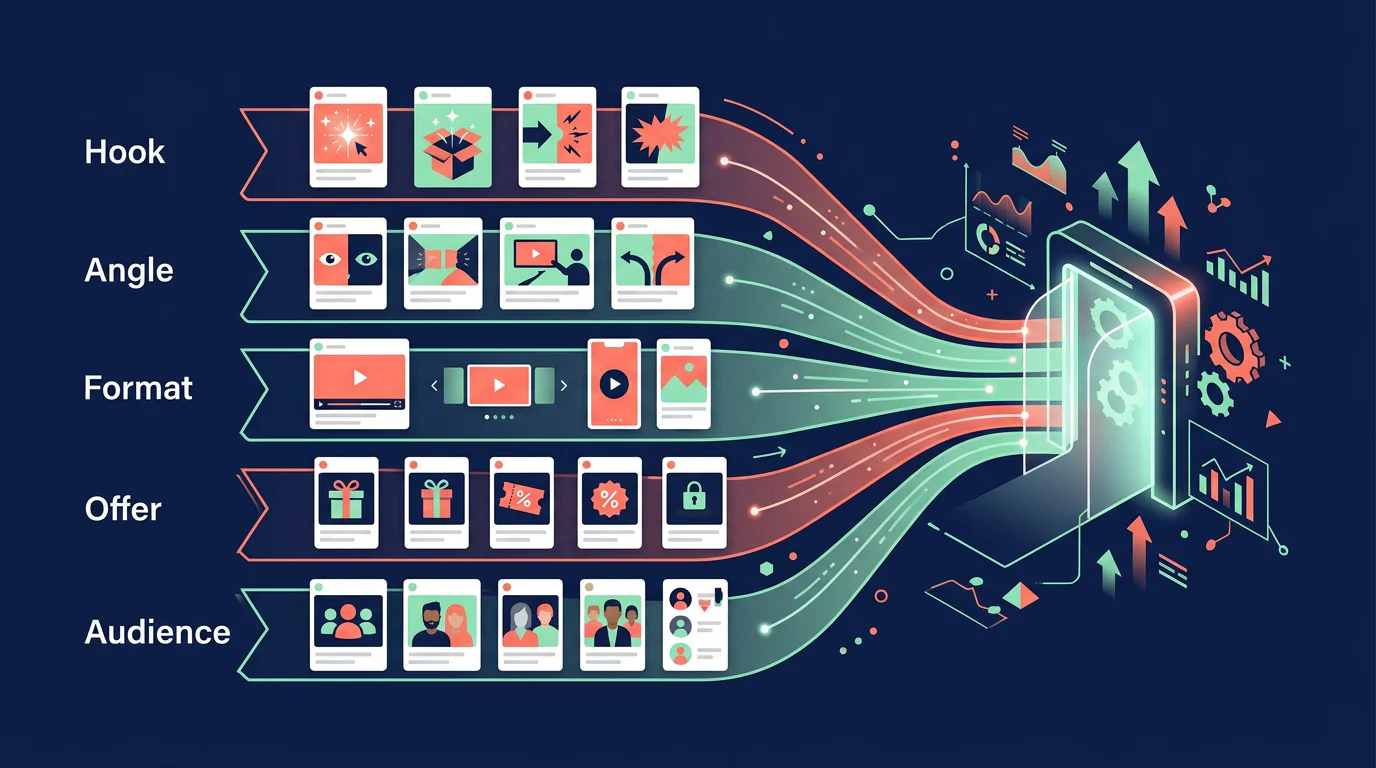
Paid social teams often say they are “testing creative” when they have changed the opening line, product claim, edit style, offer, and audience at the same time. That can produce a new ad, but it cannot produce a clean learning.
A test should isolate the reader-facing question. Is the first three seconds weak? Is the value proposition unsupported? Does a static execution lose to a video approach? Does the offer fail? Or does the audience need a different message? Those are different decisions because they create different next briefs.
| Test Type | Change Only | Hold Constant | Decision It Supports |
|---|---|---|---|
| Hook Test | Opening visual, first line, or first spoken claim | Angle, offer, audience, format | Whether the opening earns qualified attention |
| Angle Test | Core problem, promise, or objection | Offer, audience, production style | Whether the proposition improves business outcome |
| Format Test | Static, creator-style video, demo, carousel | Message and offer | Whether the execution fits the placement |
| Offer Test | Price, bundle, incentive, urgency | Creative angle and audience | Whether the commercial proposition converts |
| Audience Test | Prospecting or retargeting group | Creative and offer | Whether the message fits a defined audience |
A placement breakdown matters before any verdict. Meta has warned that placement changes can raise CTR while lowering conversion rate per click, so a team should examine total conversions and post-impression signals instead of rewarding clicks in isolation. Meta delivery update
Use angle tracking to preserve which element changed, which audience saw it, and which next brief the result supports.
What Counts as Enough Evidence to Make a Decision?
Enough evidence does not mean waiting for perfect certainty. It means the test has cleared a delivery gate and the business has a defined amount of loss it is willing to accept before taking action.
Start with the business-risk threshold. A simple ceiling can be calculated from the account’s target economics: target CPA multiplied by the minimum conversions required for a decision. Then add a delivery gate. If a video hook has had too few impressions, or a conversion test has too few conversions to compare against the baseline, it is inconclusive rather than failed.
CTR and hold rate are useful early diagnostics. They can reveal whether people are ignoring the opening or clicking without progressing. They should not overrule CPA, ROAS, qualified lead rate, or conversion value once those outcomes have enough evidence. Experimentation research separates business outcomes, diagnostics, guardrails, and data-quality measures for exactly this reason. Experiment guidance
Use this operating sequence:
- Before The Review Window: Watch delivery status, spend pace, policy status, and basic engagement for technical problems.
- At The Delivery Gate: Compare CTR, hold rate, and landing page view rate with the account baseline by placement.
- At The Evidence Gate: Compare CPA, ROAS, or qualified conversion rate after the planned minimum conversion threshold.
- At The Loss Limit: Pause only when the downside threshold is crossed and no invalidation condition is present.
This protects teams from a familiar mistake: calling a 2% CTR a creative failure without checking its placement mix, conversion rate, or delivery. It also keeps buyers from spending another week on a variant that has already exceeded the account’s acceptable downside. Use a separate kill decision process when the issue is a mature ad’s stop-loss, rather than an active controlled test.
When Should You Pause a Variant, Ad Set, or Entire Test?
The action must match the scope of the evidence. A weak result in one properly delivered variant is a variant-level decision. A simultaneous collapse across several variants is an account, ad set, offer, tracking, or delivery question until proven otherwise.
| Outcome | Evidence Required | Action | Learning Record |
|---|---|---|---|
| Stop Variant | Delivery gate passed, spend reaches ceiling, business outcome misses threshold | Pause one variant | Hypothesis not supported |
| Continue | Spend remains within ceiling and signals remain coherent | Keep running to the next review | Evidence still building |
| Extend | Enough delivery, but not enough conversions and no loss-limit breach | Extend once to a named review date | Inconclusive |
| Promote | Minimum evidence met and primary outcome beats baseline without guardrail failure | Move to controlled validation or scaling | Hypothesis supported |
| Invalidate | Tracking, policy, rendering, URL, or delivery issue undermines the result | Repair and rerun | No creative conclusion |
A team should invalidate, not stop, a test when conversion events are missing, browser and server events are incorrectly deduplicated, the destination does not load, the ad is limited by review, or delivery is materially uneven. Measurement loss can bias experiment outcomes, which makes a confident creative verdict worse than no verdict at all. Measurement research
| Pattern | Likely Scope | Next Step |
|---|---|---|
| One variant misses CPA or ROAS target while peers deliver normally | Variant | Pause the variant and record the specific hypothesis |
| Every variant weakens together | Ad set or account | Check audience, offer, landing page, tracking, and delivery |
| One variant receives nearly all spend | Delivery allocation | Treat underdelivered variants as inconclusive |
| CTR rises while CPA worsens | Message-to-conversion mismatch | Review promise, offer, landing page, and audience fit |
| Frequency rises and outcomes deteriorate | Fatigue risk | Diagnose before replacing every creative asset |
When frequency and conversion efficiency move in the wrong direction together, inspect fatigue signals before assuming the hook itself has expired.
Which Automation Should Pause, Alert, or Escalate?
Automation is most useful when it enforces a decision the team has already made. It is least useful when it tries to infer causality from a single metric in a changing auction.
We recommend three automation lanes. First, automatic pause for a single variant that has passed delivery and evidence gates, hit the spend ceiling, and breached the business threshold. Second, alert-only rules for low conversion volume, uneven delivery, or ambiguous results. Third, guarded human approval for ad-set pauses, scaling decisions, budget changes, and invalidations.
A practical rule might pause a variant when spend reaches the ceiling, conversions reach the required minimum, CPA remains above the target, and delivery status has no warning. A second rule should alert, not pause, when spend reaches the ceiling but conversion volume remains too low. A third should escalate when multiple variants fail simultaneously, because that pattern is a setup investigation.
Experiment monitoring research recommends alerts on both business outcomes and guardrails during a test. That is the useful model for paid social: automate routine protection, then preserve human judgment where context changes the answer. Monitoring research
Our automation decisions framework keeps the rule, evidence, decision owner, and reason code connected, so the team can explain why an action fired instead of merely reporting that it did.
How Do Stop Decisions Improve the Next Hook Brief?
A stop rule earns its keep when it improves the next test, not when it produces a longer list of paused ads. Each outcome should create a durable learning that is narrow enough to reuse and specific enough not to overreach.
For a stopped hook, record the audience, placement, angle, offer, baseline, spend, delivery quality, and diagnostic pattern. The useful conclusion might be, “This problem-first opening did not earn qualified attention for this prospecting audience,” not, “Problem-first hooks never work.” For a promoted hook, test one smaller variation next, such as the first frame or proof element. For an invalidated test, fix the system problem and do not enter a creative conclusion at all.
We use test memory to preserve those distinctions. A team should be able to see which format failed because it did not deliver, which angle failed after adequate conversion evidence, and which concept was never truly tested.
A simple documentation record should include:
- Test Identity: Date, campaign, ad set, variant, owner, and review window.
- Hypothesis: The one changed variable and the expected business effect.
- Baseline: Attribution setting, placement mix, primary outcome, and diagnostic benchmarks.
- Evidence: Spend, impressions, conversions, CPA or ROAS, CTR, hold rate, frequency, and delivery status.
- Decision: Stop, continue, extend, promote, or invalidate.
- Reason Code: Hook, angle, format, offer, audience, delivery, tracking, policy, or technical defect.
- Next Brief: The precise follow-up to test, avoid, or repair.
Turn Test Decisions into Deepsolv Workflows
Deepsolv helps paid-social teams preserve the reasoning behind every test, not just the winner’s ad ID. We connect creative-level performance with the hook, angle, format, offer, comments, and business outcome that produced it, so a pause becomes a usable lesson. Our workflow can surface recurring loss patterns, show whether a decline looks like fatigue or a delivery problem, and turn a valid result into a focused next brief. That matters when a team is launching weekly tests across several campaigns and cannot rely on memory or a spreadsheet full of screenshots. We still recommend human approval for material budget changes, because an account’s economics and measurement gaps need context. But we make the review faster: the buyer sees the evidence, the reason code, and the next action in one place. See how Deepsolv Creative Intelligence Software helps teams make test decisions with more confidence.
FAQs on Meta Ad Testing Framework with Stop Rules
These answers clarify the most common stop-rule questions without reducing a creative test to one engagement metric. Use them alongside the evidence gates and reason codes described above.
When Should You Stop Testing a Meta Ad?
Stop a variant after it has sufficient delivery, reaches its predefined spend ceiling, and misses the business threshold without a tracking, policy, or delivery explanation.
Should a Low CTR Automatically Pause a Creative?
No. Low CTR may signal a weak opening, but placement mix, audience saturation, or limited delivery can cause it, so compare conversion evidence before pausing.
What Does It Mean When Every Variant Fails Together?
If variants fail together, pause the conclusion, not the ad set. Check tracking, policy status, audience conditions, landing page, and delivery distribution before deciding anything.
Can Automated Rules Pause Losing Creatives Safely?
Automatically pause only a single variant that passes delivery and evidence gates. Use alerts and human approval for ad-set actions, scaling choices, and invalidation decisions.