TL;DR
We find that campaign automation can reduce production and media-operations work, but it does not automatically diagnose why creative performance changed or rank the next test. We explain how to separate actions, alerts, forecasts, and explanations, then compare automation, creative intelligence, and custom BI through evidence, maintenance, and decision accountability.
Building a custom dashboard can look inexpensive until the work behind it is visible. The U.S. mean hourly wage for computer and mathematical occupations was $57.73 in May 2025, according to May 2025 wage data, before accounting for internal overhead, data cleanup, or analyst review.
Campaign automation can remove production and media-operations work, but it does not automatically prove why an ad lost momentum or identify the highest-value next test. Treat summaries, forecasts, alerts, and automated actions as different outputs, then require evidence, prioritization, and human accountability before changing creative strategy.
We explain what this category can automate, what a credible explanation needs to show, and how to evaluate it against creative intelligence and a custom BI build.
What Does Campaign Automation Actually Automate?
Campaign automation is strongest when a team has already made the strategic call and needs reliable execution across campaigns, assets, feeds, approvals, and budgets. It can reduce repetitive work, maintain consistency, and make operational changes faster. Those are meaningful gains, especially when teams manage many assets or channels.
The mistake is treating every automated output as a strategic conclusion. A platform can pause an asset after a threshold is crossed, for example, without establishing whether the decline came from fatigue, audience saturation, a weaker offer, a landing-page mismatch, or a broader shift in demand. We use the following distinctions throughout this review.
| Output | What It Does | What It Does Not Establish |
|---|---|---|
| Automated action | Creates, updates, pauses, or scales activity using configured rules | Why that action is strategically correct |
| Alert | Flags a threshold, anomaly, or changing metric | Which cause matters most |
| Forecast | Estimates a likely future result from available signals | A causal explanation |
| Summary | Compresses performance data into readable language | A prioritized creative test |
| Explanation | Connects evidence to a plausible performance driver | Certainty without validation |
A practical review starts with the inputs behind each output. Ask what data entered the system, what threshold or model produced the result, and whether the team can trace the recommendation back to the creative, delivery, conversion, and customer evidence that supports it. That is the difference between a useful operational layer and a decision layer.
For a deeper framework on separating a delivery problem from a creative one, use our fatigue diagnosis guide before treating every declining metric as fatigue.
Does Campaign Automation Explain What to Optimize?
Current platforms increasingly describe creative analysis in terms of themes, visual elements, calls to action, summaries, and predicted performance. Those features can shorten analysis time. They are not interchangeable with a validated explanation of why an ad stopped working, nor with a ranked recommendation for what the team should produce next.
We look for a visible chain from signal to interpretation to action. If the output says an ad is underperforming, the useful next question is not simply whether to pause it. It is whether the team can see what changed, what competing explanation was ruled out, and what creative test would most efficiently reduce uncertainty.
An Alert Is Not an Explanation
An alert can be valuable when it catches a sharp CTR drop, rising frequency, worsening CPA, or a budget threshold. It tells the team where to look. It does not, by itself, tell the team whether to change the hook, the proof, the offer, the audience, or the landing page.
Creative fatigue itself should not be reduced to a single metric. A platform-level fatigue API describes a composite approach that considers CPA, cost, new-user reach rate, and other performance metrics. A useful review should therefore demand multiple signals and a clear explanation of their relationship.
A Forecast Is Not a Diagnosis
A pre-launch forecast can help a team assess attention, format fit, or likely creative effectiveness before spend is committed. That is a planning aid. It does not prove that a later performance decline came from the same factor it forecasted.
The strongest workflow compares the forecast with post-launch results, identifies where the prediction held or failed, and records the lesson. Without that feedback loop, teams collect attractive assessments without developing a reliable creative point of view.
A Useful Explanation Has an Evidence Trail
We consider an explanation actionable when it names the creative pattern, shows the relevant delivery and conversion context, states the confidence or uncertainty, and proposes a specific next action. “Refresh the creative” is an instruction. “Test a proof-led hook because click interest held while conversion quality weakened after the original claim stopped differentiating” is a testable explanation.
- Operational strength: Automating versioning, campaign updates, and budget rules can free people to spend more time on interpretation.
- Decision limitation: A summary of winning assets is not necessarily a ranked plan for what to test next.
- Evaluation standard: Ask whether the platform preserves why prior concepts worked, failed, or received an inconclusive read.
Our test memory framework shows why retaining failed and inconclusive experiments matters as much as tracking winners.
How Do Automation, Creative Intelligence, and Custom BI Differ?
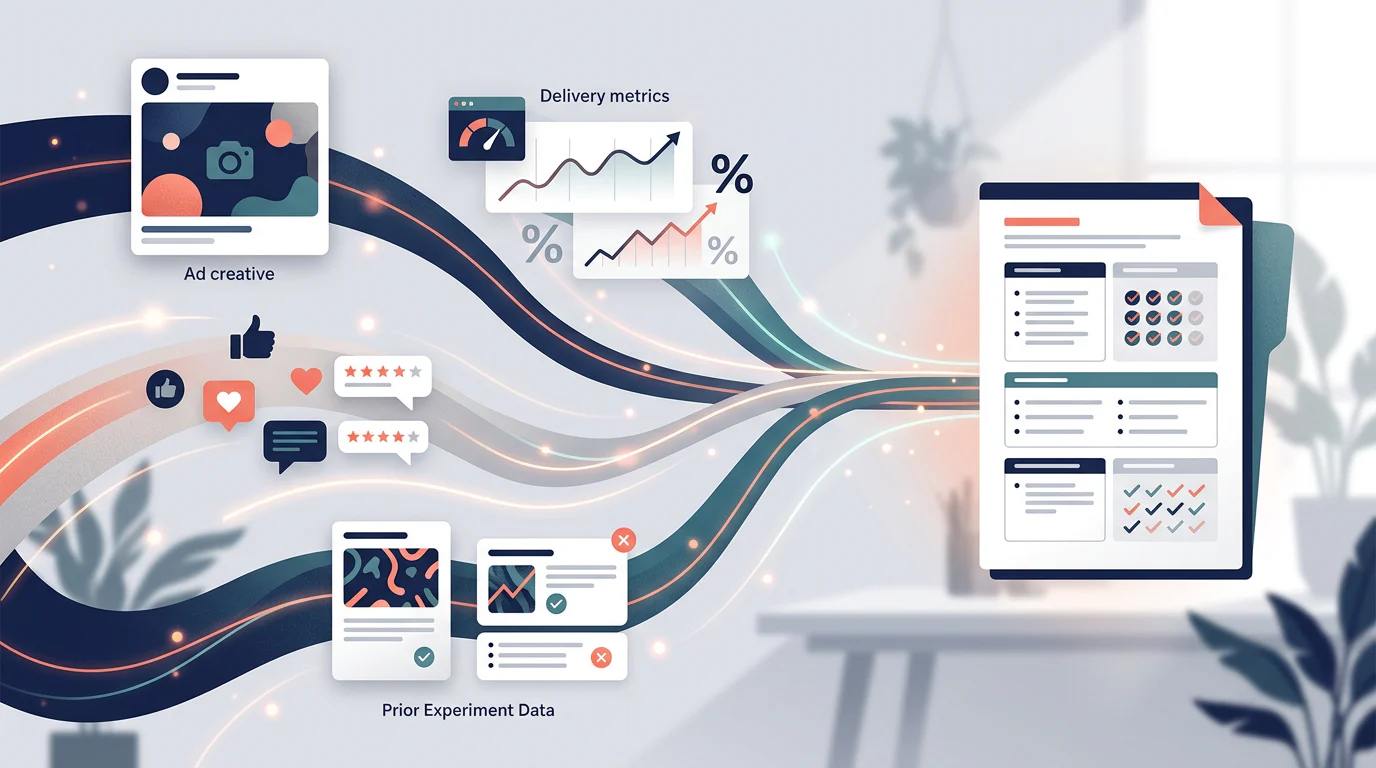
These options solve different jobs. An execution platform moves work through a campaign system. A custom dashboard reports the metrics a team models. We built our creative-intelligence workflow to connect performance, customer feedback, market signals, and prior tests into a decision about what deserves attention next.
The right comparison is not which category has the longest feature list. It is whether the category removes the team’s actual bottleneck without creating a new maintenance burden.
A consistent angle-tracking workflow gives teams a common language for comparing hooks, offers, formats, and outcomes before they decide whether a performance change requires a new concept.
| Decision Criterion | Campaign Automation | Deepsolv | Custom BI Dashboard |
|---|---|---|---|
| Core job | Execute campaign and creative operations | Prioritize creative decisions | Report defined metrics |
| Data synthesis | Campaign, creative, and media workflow data | Performance, customer, market, and test-history signals | Sources selected and modeled by the team |
| Fatigue diagnosis | Verify in a live workflow | Compare multiple signals and evidence types | Build the logic and review process internally |
| Next-step ranking | Verify action priority and evidence trail | Produce a ranked weekly test plan | Analyst-defined |
| Creative memory | Verify retention and retrieval | Retain what worked, failed, and why | Store data, with learning logic maintained by the team |
| Maintenance | Configuration, feeds, governance, and operator review | Workflow-specific onboarding and recurring evidence review | Engineering, modeling, QA, and analyst upkeep |
| Control | High operational control | High creative-decision context | High technical control |
A custom BI path offers flexibility, but its cost is broader than a dashboard license. The official licensing model includes a platform component and user licenses, with included user and API allowances varying by edition, as shown on the official licensing page. That makes a build-versus-buy conversation partly a labor and ownership conversation.
Compare Decision Quality Before Features
We recommend asking every option the same questions: Can it distinguish detection from diagnosis? Can it connect an asset to the business outcome that matters? Can it record why a test was approved? Can a new strategist understand the history without reconstructing it from exports and Slack threads?
That standard protects teams from mistaking visibility for understanding. Dashboards are useful when the question is known. Decision intelligence is useful when the problem is deciding which question, concept, or test deserves the next cycle.
Compare Workflow Automation Separately
Automation should be judged on execution: asset variation, campaign setup, publishing, budget movement, approvals, and reporting. Creative intelligence should be judged on interpretation: evidence synthesis, test prioritization, learning retention, and the quality of the brief that reaches production.
Keeping those jobs separate does not make them incompatible. It makes it possible to evaluate whether each tool is carrying the work it claims to carry. Our comparison framework provides a more detailed way to document that split.
How Should a Team Test the Two Scenarios?
A short deadline and a fixed software budget change the evaluation. They do not turn a platform’s unknown price, setup dependency, or internal labor requirement into a known quantity. We would treat the budget and timing in the buying brief as gates that must be verified in writing.
For the $3,000 monthly budget and two-week launch scenario, the crucial question is whether the tool is available within the budget, can connect to the necessary data sources, and can produce a usable workflow before the deadline. A custom build may have modest software costs while still requiring data modeling, QA, and ongoing ownership.
For the $200,000 monthly media-spend scenario, the key question changes. The team should use a real declining asset and require the vendor or internal team to show the evidence trail, competing explanations, proposed test, confidence, and learning loop. Spend alone does not prove that a platform will explain why creative results changed.
| Scenario | Evidence To Request | Decision Risk To Avoid |
|---|---|---|
| $3,000 monthly budget, 14-day deadline | Written price, data-access requirements, implementation owner, and launch plan | Treating a demo as proof of production readiness |
| $200,000 monthly media spend | One real declining asset, diagnosis, ranked next test, and feedback loop | Confusing scale with strategic clarity |
Custom warehouse costs can also vary with usage. One current warehouse pricing model includes the first 1 TiB of monthly query processing, then charges $6.25 per TiB in listed regions, but query cost is only one line item in a maintained reporting stack.
Use a repeatable decision workflow for both scenarios. It should state who owns the decision, what evidence is required, how a test will be evaluated, and what result would cause the team to stop, improve, or iterate.
What Must Be Verified Before a Commitment?
A credible review should distinguish public documentation from a hands-on validation. We evaluated the category as of August 29, 2026 using current public product materials, terms, integration guidance, platform documentation, and cost references. We do not treat a vendor claim as independently verified performance evidence.
First, verify pricing and contract structure. Some enterprise tools use order forms, spend-based fees, monthly minimums, or feature-dependent pricing, so a public list price may not exist. Second, verify implementation dependencies: ad-account permissions, pages, catalogs, feeds, attribution conventions, creative taxonomy, and the person responsible for maintaining the workflow.
Third, run a live decision test. Bring a fatigued or declining ad, then ask for the evidence behind the recommended action, the alternative explanations considered, and the precise next test. If the answer cannot be inspected, it should not be treated as a causal diagnosis.
Finally, define stop rules before launching a new concept. Our creative stop rules guide can help turn vague performance debates into a documented decision system. Keep FAQs visible and accurate if you add markup, since FAQ markup rules do not guarantee a rich-result appearance for commercial sites.
How We Help at Deepsolv
At Deepsolv, we help paid-social teams turn scattered evidence into a practical weekly creative plan. Our platform connects performance patterns, customer signals, market activity, and lessons from prior tests so strategists can see what to test, improve, or stop. We do not replace your media buying workflow or push changes into campaigns; we make the creative decision clearer before production time and budget are committed. Bring us the ads that slowed down, the customer objections your team keeps hearing, and the concepts already tried. We will help structure the evidence into a testable brief, retain the learning, and give your team a repeatable way to decide what deserves attention next. That workflow is built for teams that have campaign controls and dashboards but still need a defensible reason to choose one idea over another every week. Book a demo with us or explore Deepsolv.
FAQs on Campaign Automation
These FAQs clarify how teams should evaluate campaign automation.
Does Campaign Automation Remove Creative Decision-Making?
No. It can automate changes after rules are configured, but a strategist still needs to judge whether delivery, offer, audience, or creative caused the result.
What Evidence Should Explain a Creative Decline?
Require the asset, dates, spend, reach, frequency, conversion quality, relevant audience context, prior test history, and the specific action each signal supports before changing a brief.
Can a Custom Dashboard Diagnose Fatigue by Itself?
Not by itself. A dashboard can expose patterns, but a team must define diagnostic logic, compare competing causes, and translate evidence into a prioritized creative test.
What Should a Team Ask in a Live Evaluation?
Ask for one declining asset, the evidence trail, competing explanations, the recommended next test, confidence level, ownership, and how its eventual result updates future decisions.