TL;DR
We prioritize Meta ad concepts by evidence and learning value, not a promise that AI knows the next winner. Our framework gates off-brand ideas, clusters duplicates, sizes a workable weekly slate, diagnoses invalid tests, and records results so DTC teams can make each brief smarter than the last.
A full Figma board is not a test strategy. In 15 field experiments on Facebook advertising, observed performance often failed to match randomized results, a useful warning against treating early signals as certainty.
Meta ad concept prioritization works best when we rank ideas by expected learning value, not by a predicted winner alone. We score audience evidence, strategic relevance, novelty, brand fit, production effort, and downside risk, then choose a portfolio of proven variations, new angles, and bounded exploratory tests.
We also show how to reduce a crowded backlog into a practical weekly slate without launching near-duplicates. The framework includes capacity planning, technical diagnostics, and a feedback loop that makes each result more useful than the last.
What Should a Meta Ad Concept Scoring Table Measure?
A creative test prioritization framework should make the reason for each launch visible. It should not pretend that a neat score can replace judgment, customer knowledge, or a valid test.
We use scores to compare eligible ideas, then use Brand Brain constraints as hard gates. A concept that conflicts with an approved claim, audience priority, offer, or brand voice does not advance simply because it looks efficient to produce.
| Criterion | Decision Question | Evidence Required | Score | Disqualifier |
|---|---|---|---|---|
| Audience Evidence | Is this rooted in a repeated customer need or objection? | Customer feedback, reviews, search behavior, support themes, or account history | 0 to 4 | No evidence source |
| Learning Value | Would the result change an important decision? | A written hypothesis and next action | 0 to 4 | No decision attached |
| Novelty | Does it test a distinct message mechanism? | Similarity check against live and prior tests | 0 to 4 | Same hypothesis already live |
| Brand Fit | Does it meet Brand Brain constraints? | Approved claims, voice, audience, and offer | 0 to 4 | Unsupported or off-brand claim |
| Production Effort | Can it ship and be checked this week? | Owner, assets, approvals, placement needs | 0 to 4 | Cannot ship in the planned window |
| Downside Risk | Is the potential loss contained? | Policy, margin, reputation, and measurement review | 0 to 4 | Unacceptable commercial or policy risk |
Separate Duplicate Executions from New Hypotheses
Two Figma frames are not two concepts just because they use different creators, edits, or visual styles. We tag every idea by audience, trigger, core claim, proof, and format, then cluster ideas that answer the same question.
That discipline makes creative angle tracking more useful. Instead of concluding that five different ads failed, we can see that one unproven message mechanism failed five times in slightly different clothes.
Score the Question, Not the Mockup
A polished concept can still be low priority if it repeats an answer we already have. Conversely, a rough concept can deserve production when it tests a customer objection that keeps appearing across feedback sources.
The highest value tests usually resolve a decision: whether a new proof type earns attention, whether a distinct customer trigger changes purchase intent, or whether a proven angle can survive a meaningful variation.
Keep Brand Constraints Above the Ranking
Brand Brain is where we make strategy operational. We document which claims are supportable, which audiences matter now, what tone is acceptable, and what commercial limits apply before a concept enters the scorecard.
That keeps the weekly slate from filling with ideas that could draw clicks but weaken the brand, invite policy problems, or distract the team from the offer it actually needs to grow.
Why Can’t AI Predict the Next Winner?
AI-powered Facebook ad test planning is useful when it narrows ambiguity, not when it claims clairvoyance. It can organize evidence, identify duplicate hypotheses, surface unanswered questions, and recommend a test order that fits real capacity.
It cannot reliably certify a winner before delivery because creative is only one input to an auction that changes by person and moment. Meta describes its ad auction as combining bid, estimated action rate, and ad quality, with the estimated action rate based on machine learning.
That is why we separate two jobs. Prediction tries to name the future winner. Prioritization asks which experiment is most worth running now, given what we know, what we need to learn, and what failure would cost.
Our AI test planning approach should explain its recommendation in plain language: this concept has stronger audience evidence, is distinct from the current slate, fits the brand, and answers a question that changes next week’s decision. If it cannot explain that reasoning, the score is not yet useful.
How Do You Turn a Figma Backlog into a Weekly Slate?
The fastest way to rank a backlog of ad creative ideas is to stop treating every frame as launch-ready. First turn each concept into a structured test card, then let gates, clustering, and capacity determine the slate.
For a DTC brand spending $80,000 per month, the weekly media total is roughly $18,462 when divided across 52 weeks. That does not tell us how many concepts to launch. The feasible number depends on the account’s conversion cost, event volume, production capacity, and the evidence needed to make a responsible decision.
Normalize the Backlog
Give every concept a single record with its audience, trigger, claim, proof, format, evidence source, production owner, measurement plan, and risk status. This is the point where a loose collection of ideas becomes a decision system.
Use a weekly test prioritization routine to ensure the media lead, creative lead, and brand owner are looking at the same underlying hypothesis, not arguing about isolated visual preferences.
Rank the Concepts in Seven Steps
- Capture every concept in a shared backlog.
- Apply brand, policy, measurement, and production gates.
- Link each eligible idea to supporting audience evidence.
- Cluster ideas that test the same audience, trigger, claim, and proof.
- Write the decision the test is intended to inform.
- Score evidence, learning value, novelty, effort, and risk.
- Select a balanced slate, then retain ready alternates for technical failures.
A worked example might start with 40 concepts, remove unsupported or unshippable ideas, collapse duplicate executions into representative hypotheses, and select six distinct launches. The point is not that six is universally correct. The point is that each launch should have enough room to produce an interpretable outcome.
Set Capacity Before Choosing Winners
Before approving a slate, calculate whether each test can earn enough delivery and conversion evidence to answer its question. We use the account’s own recent cost per optimization event and predeclared decision threshold, rather than a generic conversion target.
This is also where creative testing memory matters. If a team cannot see which hypothesis already ran, under which conditions, and why the result was inconclusive, it will keep paying to rediscover the same answer.
How Should You Balance Proven Variations and New Angles?
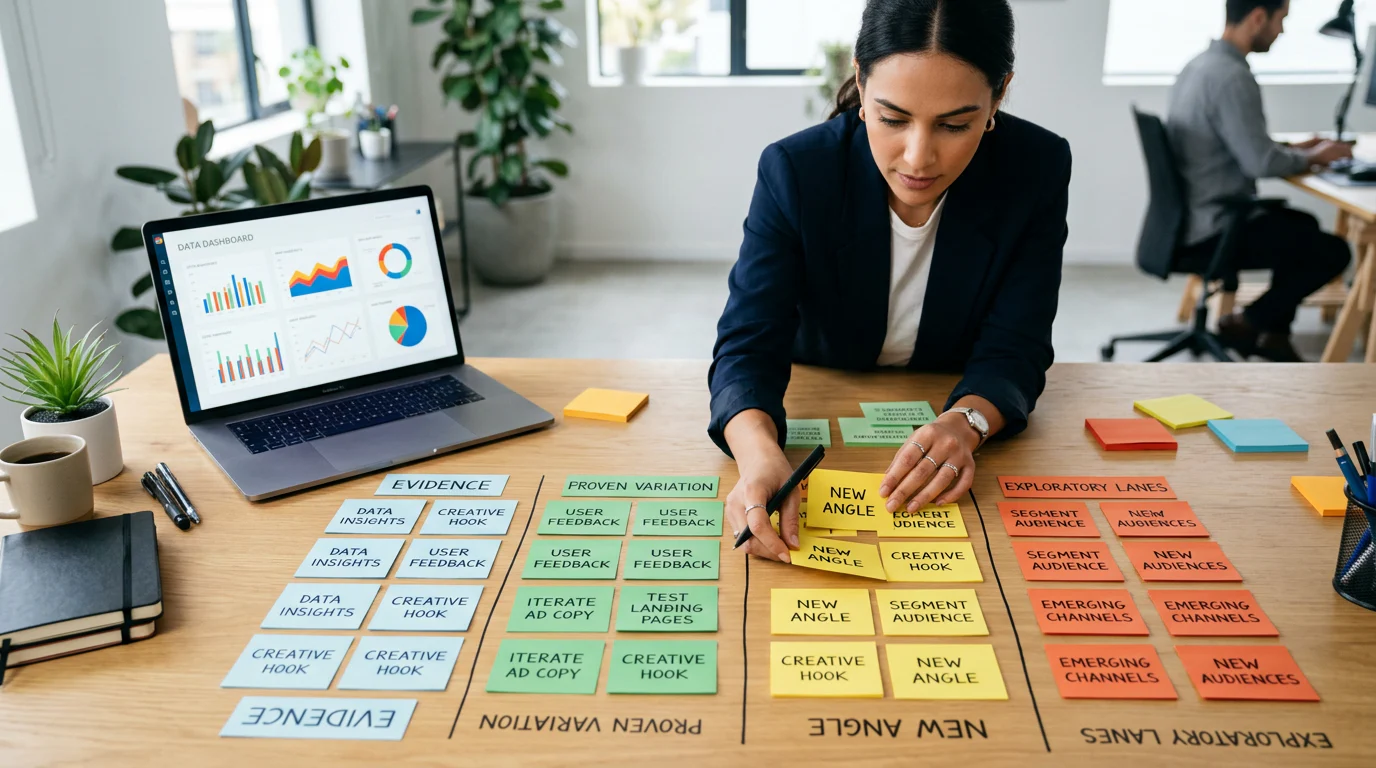
The best slate is a portfolio, not a winner-take-all ranking. If every selected idea is a minor variation of the current control, the team protects efficiency but learns little. If every idea is exploratory, the team may learn broadly but create avoidable performance risk.
We use distinct lanes so each launch has a role. The actual allocation should come from the account’s recent volatility, fatigue pattern, available production capacity, and need for discovery.
| Portfolio Lane | What It Tests | Selection Rule | Allocation Decision |
|---|---|---|---|
| Proven Variations | A meaningful refinement of a validated mechanism | Current evidence supports the core claim | Set from account performance |
| New Angles | A different customer problem, trigger, or proof | Strong audience evidence and high learning value | Set from account performance |
| Exploratory Concepts | A strategic uncertainty with bounded downside | Clear learning goal and contained risk | Set from account performance |
| Retests And Reserves | A valid question that needs a cleaner read | Prior result was inconclusive or technically invalid | Set from account performance |
Creative format can matter, but it does not erase the need for account-specific evidence. In a Meta analysis of 15 A/B tests, a particular native Reels treatment produced an average 5% lower cost per result and 11% higher conversion rate, evidence for testing the treatment rather than assuming it wins everywhere.
When a proven concept begins to lose efficiency, do not assume the angle is dead immediately. Use creative stop rules to distinguish a valid decline from a short-lived delivery issue, then keep a small pipeline of distinct challengers ready.
What Must You Diagnose Before Calling a Concept a Loser?
Before we read CPA as creative feedback, we prove that the test was eligible to teach us something. A weak result may come from the concept, but it may also come from review status, delivery, placement rendering, tracking, landing-page behavior, or an offer problem.
Confirm that the ad was approved and active, received planned spend and impressions, rendered correctly in its placements, and sent usable conversion events. Meta’s conversion guidance specifically calls out event matching, coverage, quality, deduplication, and data freshness as measurement checks.
If one of those checks fails, classify the result as an invalid test. Fix the problem and rerun the same hypothesis before lowering its evidence score or removing it from the backlog.
We also check whether a decline is fatigue, saturation, an offer change, or a creative problem. Our ad fatigue framework helps teams avoid throwing out a useful message when the real issue is frequency, audience conditions, or a worn-out execution.
How Can Deepsolv Help You Prioritize Meta Ad Concepts?
At Deepsolv, we help DTC teams turn scattered creative signals into decisions their media and creative leads can act on. Our approach connects customer feedback, account history, live performance, and brand constraints before a team asks production to make another asset. We help teams see which concepts repeat an old hypothesis, which questions remain unanswered, and which tests deserve a place in the next slate.
We do not treat an AI score as a promise. We use it to make the evidence, tradeoffs, ownership, and follow-up decision visible. That gives your team a shared record of why a test launched, what happened in delivery, and what to do next. When every result strengthens the next brief, creative testing becomes less reactive and more strategic. It also keeps useful failures from disappearing into a forgotten spreadsheet. See how we support that workflow at Deepsolv.
FAQs on Meta Ad Concept Prioritization
Should We Launch the Highest-Scoring Concepts First?
Use scores to rank candidates, then choose a balanced slate spanning proven variations, new angles, and exploratory tests that answer different important business questions each week.
Can AI Predict Which Meta Creative Will Win?
AI can organize evidence, surface duplicates, identify learning gaps, and model capacity. It cannot guarantee a winner before personalized delivery, audience response, and measurement conditions occur.
How Many Concepts Can an $80,000 per Month Brand Test?
The feasible number depends on weekly test budget, cost per optimization event, production capacity, and the amount of evidence required to make a responsible decision.
What Makes Two Meta Ad Concepts Duplicates?
Two concepts are duplicates when they test the same audience, trigger, claim, and proof, even if their creators, visuals, headlines, or edit lengths differ in format.