Ad Intelligence Alternatives That Recommend What to Test
Compare ad intelligence alternatives by public signals, connected conversions, generation, tracking, and the next creative test to prioritize.
Public ad research is valuable, but it often stops short of business results. In TikTok’s Top Ads view, video moments are indexed from 0 to 100, a precise engagement signal rather than proof of an advertiser’s sales.
At Deepsolv, we find the best ad intelligence alternatives by asking what happens after inspiration. A saved-ad tool organizes examples, a generation tool drafts variants, and a connected decision layer combines account outcomes, market changes, customer evidence, and test memory to recommend the next controlled creative test.
In this comparison, we separate public discovery from conversion evidence, explain which workflows support copy and script development, and show how teams can select concepts without mistaking observed activity for verified performance.
What Happens After an Ad Is Saved?
A discovery, swipe-file, collaboration, and briefing workflow ends when a team has examples worth discussing. The harder work starts next: classifying the hook, offer, audience pain, proof, and format, then deciding whether that pattern deserves production time.
Public libraries are useful because they make market creative observable. The Meta Ad Library says new ads and updates normally appear within 24 hours, but active status is not a conversion result. A long-running ad may be an interesting hypothesis, not evidence that it is profitable.
We use four evidence labels to keep this distinction clear:
- Observed: A public ad, offer, format, or message is visible.
- Inferred: Repetition, longevity, or prominence suggests a pattern may matter.
- Verified: Authorized first-party account data ties a creative label to outcomes.
- Tested: A controlled experiment establishes whether the change improved the defined metric.
That hierarchy prevents a team from calling an ad “winning” when it has only earned attention. For a useful account-level view, connect the labels to angle performance, not just to a gallery of examples.
Which Ad Intelligence Alternatives Complete More Work?
The best option depends on the job left unfinished after research. Some workflows help a strategist find and save examples, while others help a growth team use its own conversion history to decide what should be tested next.
| Work Completed | Primary Job | Inputs | Outputs | Winner Signal | Historical Tracking | First-Party Data | Copy Or Script Generation | Ranked Recommendations | Verified Price |
|---|---|---|---|---|---|---|---|---|---|
| Public Meta Research | Verify active creative | Advertiser, keyword, country | Searchable examples | Active status and observed longevity | Current commercial activity, with category-specific retention | No | No | No | Free |
| TikTok Creative Research | Find high-performing platform examples | Region, industry, objective, timeframe | Examples, collections, video insights | Platform metrics such as reach, CTR, CVR, and likes | Timeframe filters, not documented change alerts | No | Separate native creation tools | No | Free |
| Google Transparency Research | Verify advertiser creative and disclosures | Advertiser or website, date, location | Creative and serving context | No public downstream outcome signal | Date and last-shown visibility | No | No | No | Free |
| Connected Creative Intelligence | Prioritize a test | Market, customer, account, and test data | Ranked brief and test plan | Authorized conversion and ROAS context | Continuous market review and test memory | Yes | Draft hooks and scripts with governed inputs | Yes | Public price not listed |
Public Meta Research
Pros: We can quickly verify active creative by advertiser, keyword, and market. Limits: Public activity does not expose a rival’s revenue, CPA, or ROAS. Best For: Teams needing a free baseline for manual research before deeper analysis.
TikTok Creative Research
Pros: TikTok groups authorized high-performing examples by region, industry, objective, and timeframe, then lets researchers inspect engagement moments. Limits: The Top Ads guide describes platform signals, not a workflow that ranks a reader’s future tests from their account results. Best For: Teams researching native video structures, visual openings, and platform-specific hooks.
Google Transparency Research
Pros: We can verify where and when an advertiser served creative across major Google surfaces. Limits: It is transparency research, not a first-party creative-performance system or script generator. Best For: Teams checking messaging, advertiser disclosures, dates, and geography.
Connected Creative Intelligence
Pros: We combine permitted market activity with customer feedback, prior experiments, and authorized account outcomes. Limits: Recommendations depend on measurement quality, a consistent taxonomy, and human review. Best For: Meta growth teams deciding which concept deserves the next production slot.
For teams that only need inspiration, the simpler workflow may be sufficient. For teams that need an accountable handoff into testing, compare saved-ad options against the actual decision required.
How Do We Turn Research into a Test Plan?
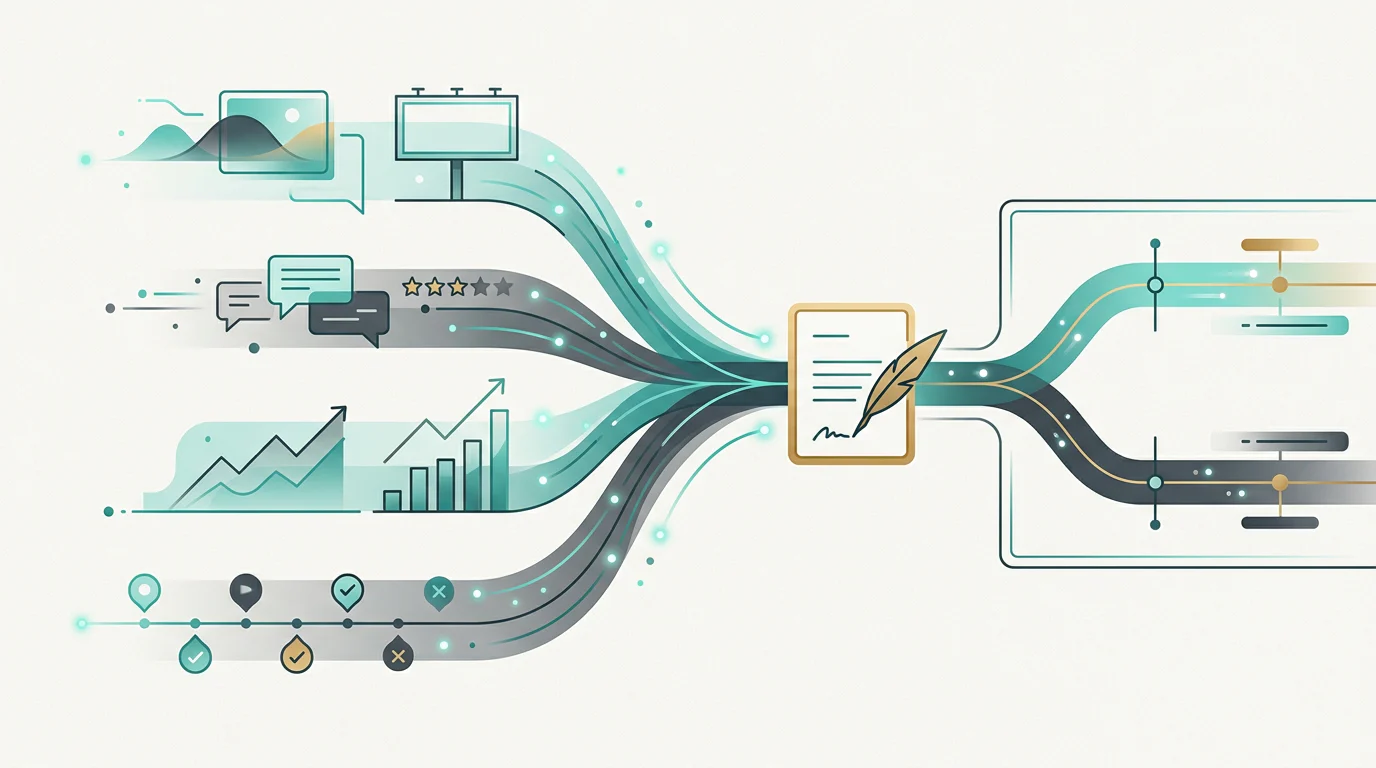
We do not treat a saved example as a strategy. We turn it into a testable hypothesis with a known audience, a clear variable, an evidence trail, and a success condition that a media buyer and creative lead can both inspect.
Classify Market Evidence
We tag hooks, promises, offers, objections, proof, audience pains, formats, creator styles, and calls to action consistently. That lets us compare patterns across creative without reducing an ad to a screenshot or a vague label such as “UGC.”
Join Labels to Owned Outcomes
A conversion ranking is only credible when it uses authorized account data under a stated definition of success. Google’s conversion guide explains that conversion values can represent business value such as revenue or profit margin, which is why clicks alone should not determine the next creative decision.
We normalize objective, spend, attribution context, timing, and conversion event before comparing concepts. A high click-through rate paired with weak purchase quality is a different outcome from a concept that converts efficiently after the click.
Draft with Brand Evidence
We use approved voice, customer language, offer constraints, landing-page proof, and prior results to draft hooks and scripts. If a proposed angle lacks those inputs, we label it a fresh hypothesis, not a proven playbook.
The brief then defines a control, one changed variable, the target audience, the evidence source, and the metric that matters. That structure helps teams set test priorities without turning every new idea into a full production request.
Before results arrive, we also define what a fair read means. That includes the budget, run time, attribution rule, and minimum signal needed before a team calls a concept weak, promising, or ready to scale.
Retain the Learning
After the test, we preserve what worked, what failed, what fatigued, and what was never fairly evaluated. We retain the evidence beside the creative decision so the next planning cycle starts from a specific learning instead of a vague recollection.
What Should Teams Verify Before Choosing?
A useful evaluation is less about the longest feature list and more about whether the workflow can support the next decision. We recommend asking what evidence the platform accepts, what it can prove, and what a team can actually export or act on. That process becomes more reliable when teams preserve a shared testing memory rather than starting every review from scratch.
| Evaluation Area | Public Research Workflows | Connected Decision Workflow |
|---|---|---|
| Supported Networks | Individual platform libraries and transparency centers | Confirm account and market coverage during setup |
| Export Options | Search, sharing, saved collections, or category-specific reports | Decision-ready briefs and evidence trail |
| Best-Fit Team | Strategists collecting inspiration | Growth teams prioritizing paid social tests |
| Pricing And Trial | Free access for platform-native research | Scope and pricing confirmed directly |
| Winner Definition | Activity, selection threshold, or platform metric | Authorized conversion, value, and ROAS context |
| Historical Change | Manual snapshots or date filters | Continuous review plus retained test learning |
We also ask whether a tool tracks competitor messaging as a moving pattern rather than a one-time capture. First seen, last seen, offer refreshes, hook changes, and repeated formats matter because a category can shift before a dashboard makes the change obvious.
A selection process should identify the operating constraint before comparing software. If the real bottleneck is generating options, production support may be enough. If the bottleneck is deciding what deserves budget, the team needs a system that can keep the reason for each recommendation visible through planning, launch, review, and the next cycle.
We begin that work with strategy selection, documenting the team’s decision owner, evidence standard, conversion definition, and required approval path before any data connection is evaluated.
That preparation requires more than account credentials. Teams need aligned creative naming, clear ownership of conversion definitions, a review cadence, and a decision-maker who can distinguish an early signal from a finished result. They also need a practical escalation path for claims, offer changes, landing-page mismatches, and incomplete data. Without those operating rules, a promising creative insight can still become an unproductive production request, a misleading dashboard conclusion, or a test that nobody can interpret consistently.
Measurement access also requires planning. TikTok lists direct Event API or combined Pixel and Event API implementations as taking one to four weeks, depending on the approach, so teams should confirm ownership and data readiness before expecting conversion-ranked recommendations.
Once those conditions are clear, we compare public market observations with account outcomes through a disciplined signal comparison. That keeps category activity useful without allowing it to overrule the performance evidence that belongs to the advertiser.
Why Deepsolv Recommends What to Test
Deepsolv is built for growth teams that already have ideas, assets, and reporting, but still need a defensible answer to “which concept earns the next production slot?” We bring permitted competitor activity together with customer comments, account results, and prior tests, then keep the evidence attached to each recommendation. Our output is a weekly plan that names the audience, hook, offer, format, control, success metric, and reason to test, iterate, or stop. We do not treat a public ad as proof of a rival’s revenue. We use it as market context, then let your authorized data show what worked for your brand. That gives media buyers and creative leads one shared decision trail, while preserving the human judgment needed for claims, taste, and final approval before budget and studio time are committed to your next weekly test. See how Deepsolv.
FAQs on Ad Intelligence Alternatives
These answers clarify the evidence standard we use when comparing workflows for research, creative development, and performance-led test planning.
Which Ad Intelligence Alternatives Identify Winners by Conversions?
Only platforms connected to authorized account, revenue, or attribution records can rank ads by downstream conversions. Public research offers context, but cannot verify another advertiser’s sales.
Can Public Ad Research Prove a Competitor's ROAS?
No. It can show creative, dates, activity, and selected platform signals. ROAS requires advertiser cost and conversion value data, measured under a defined attribution rule.
How Should Generated Hooks Use Brand Evidence?
We treat generated hooks as drafts. Before approval, we use approved voice, customer evidence, prior learning, offer constraints, and landing page proof to avoid unsupported claims.
What Belongs in a Ranked Test Recommendation?
We include the audience, hypothesis, control, changed variable, evidence source, success metric, attribution rule, and scale condition. Teams can then execute and audit the recommendation.