Which Saved-Ad Alternatives Go Beyond Swipe Files?
Compare swipe-file alternatives for competitor history, customer objections, conversion evidence, and creative briefs.
Creative research matters when it improves the next test, not when it adds another folder of examples. In a platform-reported analysis of 15 A/B tests, a vertical-video setup produced an average 5% lower cost per result and 11% higher conversion rate.
The best swipe-file alternatives depend on what must happen after an ad is saved. Choose historical tracking to detect hook and offer changes, customer-signal analysis to uncover objections and language, connected performance analysis to rank your own proven patterns, or drafting tools to turn evidence into testable hooks and scripts.
We will show where each workflow fits, what evidence it can support, and how to choose a system that moves research into accountable creative decisions.
What Do Swipe-File Alternatives Need to Do Beyond Saving Ads?
Saving examples is still useful. It gives creative teams a searchable record of formats, claims, visual devices, offers, and landing-page patterns worth studying. But a saved ad is an observation, not a verified explanation for why it worked.
The practical question is what your team needs after discovery. If you need to monitor a category, save time by tracking changes. If you need stronger messaging, bring in customer language. If you need to allocate budget, connect the analysis to authorized account outcomes. Our creative intelligence software is built around keeping those evidence types distinct, then using them together to prioritize the next test.
| Need After Saving An Ad | Evidence Needed | Useful Output | What It Cannot Prove |
|---|---|---|---|
| See market movement | First and last observed dates, creative versions, destinations | Change alert and timeline | Another advertiser’s profitability |
| Understand buyer language | Permitted comments, reviews, support, and survey data | Objection and proof themes | Conversion causality |
| Prioritize account patterns | Authorized delivery, event, and revenue records | Conversion-aware test ranking | Incrementality without validation |
| Produce new creative | Evidence-linked research and brand context | Hooks, scripts, briefs, and test hypotheses | That generated copy will win before testing |
A good system also preserves the path from source to conclusion. Teams should be able to see which ad, customer statement, account result, or prior experiment led to a recommendation, then disagree with the recommendation without losing the underlying record.
How Do You Track Competitor Messaging Changes over Time?
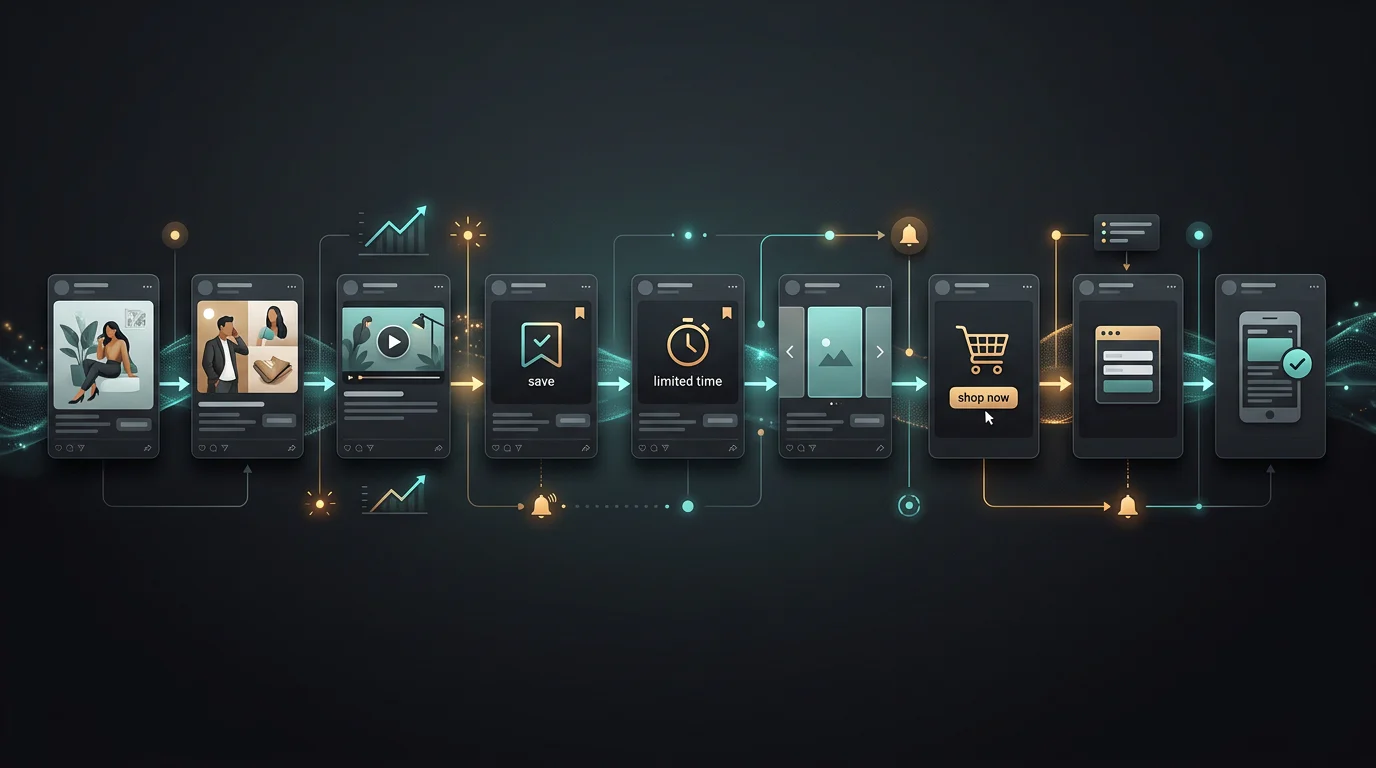
One-off research captures a moment. Historical tracking captures the sequence: a new hook, an offer revision, a different landing page, a format shift, or a familiar concept appearing across several executions. That sequence is usually more useful than a large gallery because it distinguishes a fleeting experiment from a pattern worth investigating.
Our approach starts with permitted public records and records when we observed them. We do not treat a newly visible ad as proof that it is newly launched, scaled, or converting well.
Record the Fields That Make a Change Useful
Track the first observed date, last observed date, advertiser, region, destination, format, hook, offer, audience hypothesis, and asset relationship. A shared taxonomy matters because a renamed asset should not become a false new concept.
Alert on Meaningful Movement, Not Every Edit
Useful alerts identify a changed offer, a new promise, a landing-page pivot, a notable format switch, or repeated use of one angle. An alert should include the evidence and a proposed research question, rather than making an unsupported claim about strategy.
Separate Repetition from Performance
Repeated activity can justify attention. It cannot establish spend, cost per acquisition, revenue, or return on ad spend for an outside advertiser. We use repeated observations to create sharper hypotheses, then validate them in the account we are authorized to analyze through continuous competitor tracking.
How Can Customer Signals Explain the Objections Behind an Ad?
Customer signals make a swipe library more strategic because they show how people describe the problem in their own words. Comments, reviews, support conversations, surveys, and permitted public discussions can reveal confusion, trust gaps, desired outcomes, and proof requirements that a creative team can address.
The data must be handled responsibly. The FTC guidance on reviews and testimonials explains that its rule took effect on October 21, 2024 and addresses deceptive or unfair review practices. We use genuine, permitted source material, preserve context, and avoid treating isolated sentiment as a market-wide conclusion.
Turn Language into Testable Creative Inputs
We group recurring phrases into themes, then map each theme to a creative decision. “Will this work for someone like me?” may require audience proof. “Why is it worth the price?” may require value framing. “How quickly will I see a result?” may require expectation-setting instead of a louder promise.
Keep Customer Signals and Performance Separate
A comment may explain why an ad attracted attention. It does not prove that the ad generated qualified demand or revenue. We pair customer-language themes with our ad comment analysis, then evaluate the resulting creative hypothesis against a defined account metric.
Protect the Source Context
Customer information used for profiling or marketing analysis needs an appropriate lawful basis, clear disclosure, accuracy, and proportionality. The ICO guidance makes those obligations explicit. Our workflow keeps the evidence, action, and owner connected without turning customer data into an ungoverned prompt.
Which Signals Actually Show That an Ad Pattern Is Winning?
The word “winning” becomes misleading when it hides the source of the claim. Longevity, engagement, spend proxies, platform attribution, and controlled tests answer different questions. Our performance evidence stays separate from public market observations, so the recommendation remains honest about what it knows.
| Evidence Level | What It Can Show | Best Use | Important Limitation |
|---|---|---|---|
| Visible activity | An ad or format was observable over time | Market discovery | No private spend or revenue |
| Engagement | Audience reaction or attention | Message and format hypotheses | Attention is not conversion |
| Modeled proxy | A directional estimate under a stated method | Triage and research | Model uncertainty remains |
| Connected conversion data | Your account’s defined outcomes | Ranking owned creative patterns | Attribution is not causality |
| Controlled validation | Incremental effect under a test design | Scaling decisions | Requires test discipline |
Public ad repositories improve transparency, but their scope does not turn public creative into private business reporting. The EU transparency rules require clearer information about advertising, including who placed it and why it is shown, not access to an advertiser’s conversion ledger.
For performance teams, we recommend joining a stable creative ID to account delivery, conversion event, and revenue records, while retaining attribution window, campaign objective, and reporting date. Our conversion-ranked evidence framework makes those boundaries visible. It also prevents a high-click asset from outranking a lower-click asset that produced more valuable downstream outcomes.
How Should You Choose Between Swipe-File Alternatives?
Choose the workflow that resolves your actual bottleneck. A competitor strategist who needs a messaging timeline has a different problem from a customer researcher who needs objection clusters. A copywriter needs an evidence-backed brief, while a performance team needs reliable joins between creative labels and downstream outcomes.
| Capability | Saved-Ad Library | Change Monitor | Customer-Signal System | Account Performance System | Generation System | Deepsolv |
|---|---|---|---|---|---|---|
| Timeline And Version History | Limited | Core capability | Limited | Account-only | Limited | Tracks observable market changes |
| Offer-Change Detection | Manual | Core capability | No | No | No | Connects changes to test hypotheses |
| Customer Signals | Usually absent | Usually absent | Core capability | Limited | Prompt-dependent | Uses permitted feedback with context |
| Downstream Performance Connection | No | No | No | Core capability | No | Uses authorized account evidence |
| Hooks, Scripts, And Briefs | Limited | Limited | Limited | Limited | Core capability | Drafts evidence-linked test plans |
| Integrations And Exports | Varies | Varies | Varies | Varies | Varies | Confirm scope for your workflow |
| Collaboration And Multi-Brand Use | Varies | Varies | Varies | Varies | Varies | Confirm roles and operating model |
| Pricing | Varies by provider | Varies by provider | Varies by provider | Varies by provider | Varies by provider | Contact us for current scope |
The most complete option is not always the right one. Use a focused library for inspiration, a monitoring workflow when timing matters, a customer-signal process when language is missing, and connected account analysis when the decision affects budget or production capacity.
When the goal is a weekly decision, we recommend a simple production standard: name the source, state the hypothesis, choose one variable, define the success metric, and record the scale or stop condition. Our angle tracking keeps that standard connected to a durable record of what changed and what happened next.
Why Deepsolv Fits a Connected Research Workflow
At Deepsolv, we built our workflow for teams that have outgrown collecting examples but still need a clear next creative decision. We bring permitted market observations, connected account outcomes, customer language, and past experiments into one evidence trail. That lets us show what is visible, what is verified in your account, and what remains a hypothesis worth testing.
Our output is not another gallery or a generic batch of copy. We turn the evidence into a ranked test plan with a hook, offer, format, supporting proof, owner, and scale or stop condition. We also preserve source context and the decision record so the next planner can challenge or reuse the conclusion. Your team can keep the learning when a test wins, loses, or needs another iteration, instead of repeating last quarter’s research. If your decision process needs sharper inputs and a durable testing memory, book a demo
FAQs on Swipe-file Alternatives
What Can Saved Ads Prove About Performance?
Saved ads reveal messaging, timing, visible formats, and sometimes engagement. They do not reveal another advertiser’s private conversion events, costs, revenue, attribution choices, or profitability.
How Do I Track a Competitor’s Hook Changes over Time?
Record first observed and last observed dates, preserve the creative and destination, classify its hook and offer, then alert only when a meaningful difference appears.
Can Customer Comments Identify Creative Objections?
Yes, when comments are permitted and interpreted in context. Group recurring language into objections, desired outcomes, trust gaps, and proof needs before drafting creative hypotheses.
Does Engagement Prove an Ad Converted?
No. Engagement measures attention and reaction, whereas conversions measure a defined business action within a stated attribution model. Treat engagement as a hypothesis signal, not proof.
What Data Ranks Ads by Conversion Performance?
Connect immutable creative IDs to authorized account, event, and commerce data. Compare outcomes using consistent conversion definitions, attribution windows, objectives, reporting periods, and minimum observation thresholds.
Can AI Draft Scripts from Verified Account Learnings?
Yes, when it receives documented creative patterns, customer language, and authorized outcomes. Drafts still require human review, brand judgment, and a defined test plan before launch.