Which Meta Ad Concepts Should You Test First? Meta Ad Concept Prioritization
TL;DR
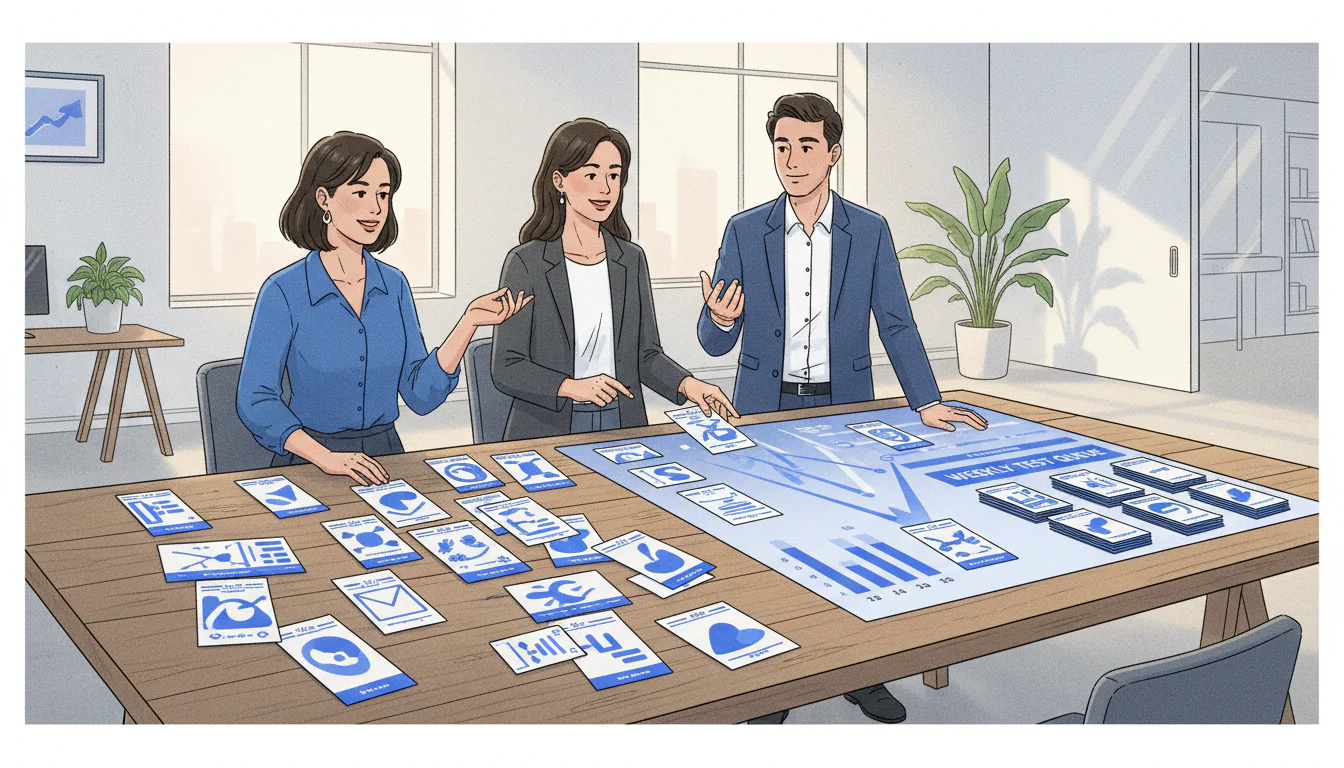
We use Meta ad concept prioritization to turn a crowded creative backlog into a funded test queue. We score distinct hypotheses by evidence, strategy, novelty, feasibility, brand fit, and learning value, then sequence them around controls and conversion capacity. AI can organize and rank the work, but valid exposure is still what tells us which creative deserves more budget.
Meta says performance typically stabilizes after around 50 optimization events within seven days. That makes a crowded Figma backlog a planning problem before it becomes a media-buying problem.
Meta ad concept prioritization should start with expected information value, not creative preference. We score audience evidence, strategic relevance, novelty, production feasibility, brand fit, and learning value, then fund the highest-ranked distinct hypotheses. We also reserve controls so multiple executions do not spend against the same assumption.
This guide shows us how to define a distinct concept, reduce duplicates, balance exploration with proven angles, and use AI without confusing organization with prediction.
How Does Meta Ad Concept Prioritization Turn Ideas into a Funded Queue?
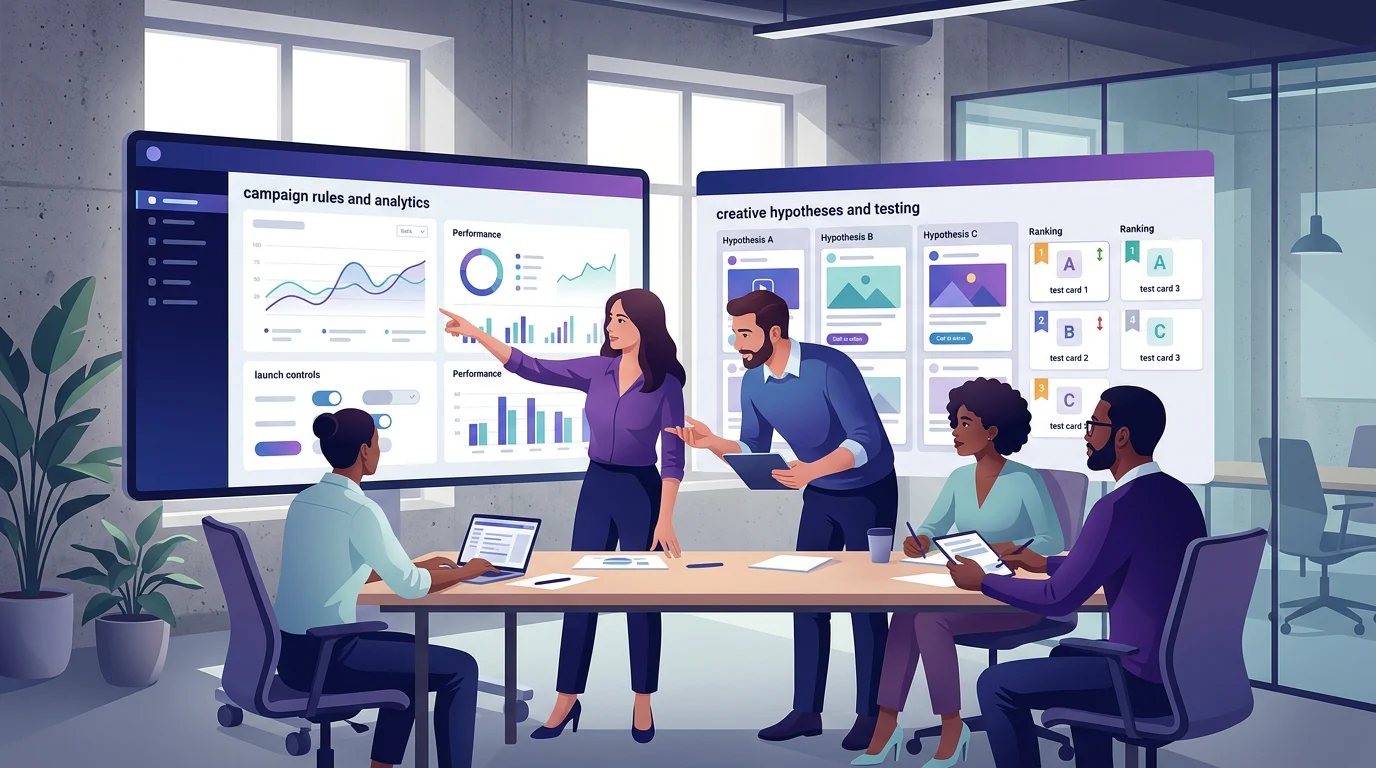
When we have 40 concepts and a limited number of valid test opportunities, the question is not which idea looks strongest in a review meeting. The question is which distinct hypothesis is most worth learning from now. Our scorecard makes that decision visible, repeatable, and accountable.
| Scorecard Input | What We Evaluate | Weight |
|---|---|---|
| Customer Evidence | First-party comments, reviews, surveys, support themes, and prior tests | Brand-Verified Weight |
| Strategic Relevance | Current positioning, offer, funnel problem, and business priority | Brand-Verified Weight |
| Novelty | Distance from recently tested hypotheses | Brand-Verified Weight |
| Production Feasibility | Asset readiness, approvals, production time, and landing-page readiness | Brand-Verified Weight |
| Brand Fit | Approved claims, voice, audience, and prohibited directions | Brand-Verified Weight |
| Learning Value | The size and usefulness of the next decision a result could unlock | Brand-Verified Weight |
Start with Evidence
A high score for customer evidence means we can point to a real signal, not merely a plausible idea. We look for repeated language in customer feedback, a demonstrated conversion pattern, a recurring objection, or a meaningful gap in what we have already tested. A visually polished concept with no evidence can still enter the queue, but it should compete as exploration rather than inherit confidence it has not earned.
Let Brand Brain Set the Boundary
Our Brand Brain inputs come before creative scoring. They constrain who we speak to, what we can credibly claim, the voice we use, the positioning we protect, and the directions we will not publish. That prevents a high-scoring performance idea from becoming a brand-costly experiment.
Make the Score Auditable
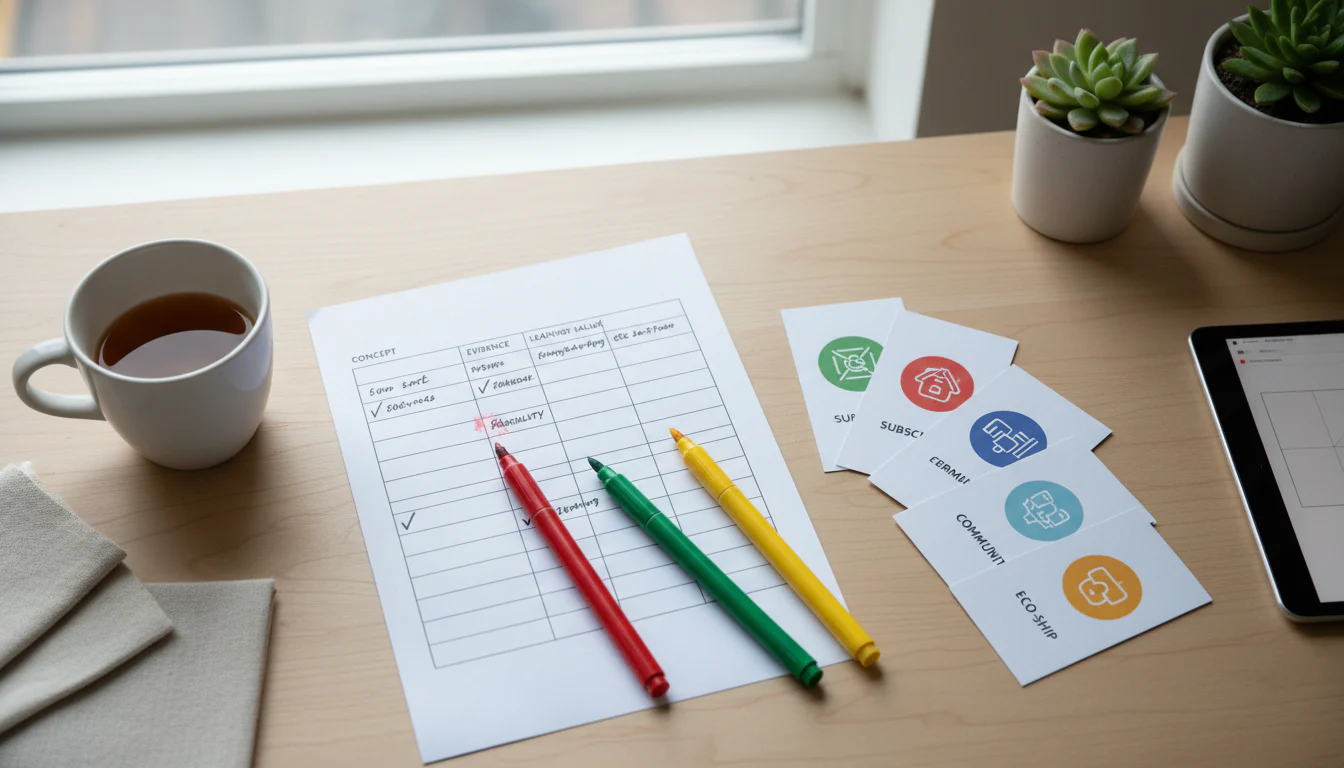
We keep a short rationale beside every score. The sheet should include the concept ID, source evidence, underlying hypothesis, control, production owner, planned KPI, stop rule, and next decision. We also require the approved weights to total 100 percent before the queue sorts. That turns the scorecard into a decision record, not a decorative spreadsheet.
A concept with modest confidence can rank first if it resolves a large strategic question. A near-copy of a recent winner can rank lower when it adds little new learning. For launch decisions after concepts enter the queue, use creative test stop rules so urgency does not replace pre-agreed judgment.
What Counts as a Distinct Concept?
A concept is the proposition we want the market to answer. It is not every visual treatment, headline, or edit that happens to appear in the backlog. When we name the layers correctly, we stop spending as though cosmetic variety equals experimental variety.
| Layer | What It Means | Example Decision |
|---|---|---|
| Concept | The testable proposition connecting an audience tension to a promise | Does proof of easier setup reduce hesitation? |
| Angle | The persuasion route used to express the concept | Ease, trust, speed, or value |
| Hook | The opening device that earns attention | A question, contrast, demonstration, or customer quote |
| Execution | The specific script, creator, visual treatment, and edit | Creator-led demo with close product shots |
| Format | The delivery shape of the asset | Static, carousel, or short-form video |
| Isolated Variable | The deliberate difference from the control | Opening hook only |
Deduplicate by Hypothesis, Not Visual Treatment
Three Figma cards can look entirely different while testing the same belief. A creator testimonial, product demonstration, and static quote may all assert that social proof resolves the same objection. We group them under one hypothesis, choose the most production-ready execution for the first test, and save the rest for follow-up iteration.
This distinction gives us a cleaner history of what audiences actually responded to. It also makes angle performance tracking more useful because we can compare message-level learning rather than only compare asset IDs.
Decide What the Result Would Change
We ask one practical question before keeping a concept separate: if this wins or loses, will we make a different next decision? If not, it is probably an execution variant, not a new test. A new angle may deserve its own round. A new hook inside an already supported angle may belong after that angle has earned more attention.
We preserve the hierarchy by linking each asset result to the customer tension, proof type, and decision it was meant to inform. That record ensures a creative library becomes a source of learning rather than an archive of disconnected uploads.
How Should We Balance Explore and Exploit Tests?
We need both types of work. Exploit tests build on a supported hypothesis, such as refining the hook, proof, or format of an established winner. Explore tests challenge our current understanding with a new audience tension, promise, proof mechanism, or creative route.
Meta encourages creative diversification, and its published Reels analysis covered 15 A/B tests across multiple markets. That does not tell us which format will work for our brand, but it does support treating format as a deliberate variable rather than an afterthought.
| Queue Type | Best Use | Evidence Requirement | Typical Next Decision |
|---|---|---|---|
| Exploit | Improve or extend a supported hypothesis | Strong prior performance or repeated customer evidence | Iterate the winning execution |
| Explore | Test a materially new strategic assumption | Plausible evidence and high learning value | Validate, reject, or redesign the angle |
| Control | Anchor a comparable round | Current relevant baseline | Separate market movement from creative change |
We do not let exploit work consume the entire queue simply because it feels safer. It can produce useful gains, but it can also trap us in an exhausted message. Conversely, exploration without a control can make every noisy result look meaningful.
When a former winner declines, we inspect delivery, audience, offer, placement mix, technical problems, and feedback before calling it fatigue. That is why we pair this planning framework with a creative fatigue diagnosis, rather than treating every decline as proof that we need more concepts.
How Do We Sequence Concepts Around Spend and Conversion Capacity?
A monthly budget does not tell us how many concepts we can test at once. Expected CPA, the chosen optimization event, the number of cells, production capacity, and the available test window determine that. For the $80,000 monthly scenario, daily spend is about $2,630, but that amount still needs to support live controls and qualifying conversion volume.
Build the Weekly Queue in Five Steps
- Capture every concept with its customer or performance evidence.
- Apply Brand Brain constraints before any ranking happens.
- Collapse duplicate executions into distinct hypotheses.
- Score the remaining concepts, then reserve a relevant control.
- Fund only the cells that production and expected conversion volume can support.
Protect the Exposure Needed to Learn
We estimate required spend from the expected cost of the optimization event and the amount of exposure needed to make the planned decision. If the budget cannot support every cell, we narrow the round instead of spreading spend across every available asset. We preserve the calculation and decision in creative testing memory, so the next queue can distinguish a new strategic question from one we have already answered.
Meta advises setting a sufficient budget for at least seven days. We use that guidance as a sequencing constraint, not a reason to keep an invalid test alive after an approval, delivery, or tracking failure.
Write the Decision Before Launch
Every funded item gets a completed test card:
| Test Card Field | Completed Example |
|---|---|
| Hypothesis | A product demonstration that answers the main setup objection will improve purchase efficiency against our testimonial control. |
| Variable | Opening sequence, demonstration first versus testimonial quote first |
| Audience | The same prospecting audience used by the current control |
| KPI | Cost per purchase, with purchase conversion rate as a diagnostic metric |
| Stop Rule | Pause immediately for rejection, broken conversion events, material landing-page changes, or confirmed technical failure. Otherwise, read results at the planned exposure point. |
| Next Decision | Scale the supported route, refine the execution, or replace the hypothesis with a more distinct one. |
We connect the resulting evidence to a paid-social signal-to-action workflow, so a completed test card becomes the start of the next planning cycle rather than a forgotten launch note.
What Can AI-Powered Test Planning Do, and What Can It Not Do?
We use AI to make the backlog easier to reason about. It can cluster similar concepts, extract recurring customer language from approved inputs, flag missing controls, identify novelty gaps, draft test cards, and estimate whether a proposed queue fits the production plan and media constraints.
What it cannot do is know the causal winner from an unexposed creative file. A 2023 research study covering more than 250 randomized A/B comparisons found that historical-data models can improve analytical precision. That is valuable, but it is not a license to convert a model score into a winner claim.
The useful promise is better test planning, not a black-box forecast. We want AI to make our reasoning more consistent, ensure Brand Brain constraints are applied, and surface the most decision-rich concepts before money moves. We still need valid delivery, measurement, and comparable exposure to learn whether a creative changed the outcome.
Use AI test planning to organize the weekly queue, then use the actual result to update the next hypothesis. That division of labor keeps our planning fast without making our conclusions fragile.
How Deepsolv Supports Better Meta Ad Concept Prioritization
At Deepsolv, we help DTC teams turn scattered comments, performance signals, and creative ideas into a decision-ready queue. Our workflow keeps Brand Brain constraints visible before a concept becomes a brief, then preserves the hypothesis, variable, control, and next decision after launch. That means the next weekly planning meeting begins with what the brand has learned, not a hunt through Figma files, dashboards, and memory. We do not ask teams to trust a black-box winner forecast. We help them make the reasoning behind a test explicit, identify duplicate assumptions, and keep a clean record of what earned more budget, what needs a new execution, and what should stop. It gives creative, growth, and brand leads one shared operating record for every launch. If your paid-social team needs a stronger bridge from customer signal to funded creative experiments, visit our homepage.
FAQs on Meta Ad Concept Prioritization
How Should a DTC Brand Choose from 40 Concepts?
We collapse visual variations into distinct hypotheses, score evidence and learning value, reserve a control, then fund only cells with enough planned exposure for interpretation.
Can AI Predict Winning Meta Creative?
We use AI to organize evidence, identify duplication, and draft comparable test cards. It cannot know causal lift before valid exposure and measurement establish it.
What Should a Test Card Include?
We document the hypothesis, isolated variable, audience, KPI, control, stop rule, validity checks, and next decision, so every result changes a future choice with accountability.
Why Did a Creative Stop Performing?
We check delivery, approval status, placement mix, offer changes, technical problems, and feedback before calling a decline fatigue, then plan the next distinct hypothesis carefully.