TL;DR
We separate campaign automation from creative strategy: operational tools can launch, rotate, and report, while our platform ranks what to test next from performance, market, customer, and test-history signals. This review shows where a custom dashboard fits, why a two-week launch has dependencies, and how teams turn fatigue into evidence-backed creative decisions.
Most paid-social teams can already see performance, yet reporting must be modeled before it can answer creative questions. For example, a standard dashboard instance includes 10 Standard users and 2 Developer users under an annual commitment, according to Google pricing.
A creative automation review should separate operational automation from strategic synthesis. Choose a campaign platform when the next move is launching, rotating, or reallocating. Choose our platform when the team needs a ranked creative hypothesis grounded in performance, market, customer, and test-history signals. Build a dashboard only when analysis capacity already exists.
We audit the difference, compare the three jobs, and show what a team can realistically make live in two weeks without pretending that an undisclosed price is a verified cost.
Does a Creative Automation Review Need More Than a Dashboard?
The gap is not whether a team has data. It is whether the team can turn data into a defensible decision before the next creative brief is due. A fatigue alert can show that something is changing, but it cannot independently explain whether to refresh an asset, alter delivery, or test a new message.
Public competitor context also has limits. The Meta Ad Library shows currently active ads for all advertisers, while seven-year inactive history is generally reserved for issue, electoral, and political ads. That matters when a platform claims broad market intelligence.
| Decision Job | Campaign Platform | Our Platform | Custom Looker Dashboard |
|---|---|---|---|
| Media Automation | Launches, rotates, and optimizes campaigns | Not a media-buying tool | No native execution |
| Reporting | Provides campaign reporting | Connects performance to creative decisions | Strong when data is modeled |
| Creative Production | Scales templates and variations | Produces evidence-led briefs and concepts | No native production |
| Fatigue Detection | Can flag or automate a media response | Uses fatigue as decision evidence | Possible with custom models |
| Strategic Recommendations | Verify output and evidence in a demo | Ranks weekly creative tests | Requires custom logic |
| Competitor Context | Not always documented publicly | Uses competitor movement as an input | Requires an external pipeline |
| Customer Evidence | Not always documented publicly | Uses approved feedback signals | Requires ingestion and governance |
| Historical Creative Tagging | Varies by setup | Connects prior tests and outcomes | Requires a maintained taxonomy |
| Setup | Accounts, assets, rules, and permissions | Confirm current integration scope | Warehouse, model, version control, alerts |
| Verified Price | Quote required | Quote required | Annual, quote-based pricing |
For teams that already have reporting, the practical question is simple: do you need another view of the data, or a recommendation for what to make next? Start by separating fatigue from the diagnosis with our fatigue diagnosis framework.
What Counts as a Strategic Recommendation?
A recommendation is not merely a notification written in a more confident tone. It should name the proposed action, connect it to evidence, explain why it matters now, assign an owner, and define what will prove or disprove the hypothesis.
That distinction is why this Creative Automation Review focuses on decision layers rather than a generic feature checklist. The same performance decline can produce three valid actions, depending on what caused it.
A Media Action
A media action changes delivery. It may pause an underperformer, rotate an existing variant, alter budget allocation, or apply a predefined rule. This is valuable operational automation, especially when a team manages campaign volume that makes manual intervention slow.
It is not automatically a creative recommendation. The action may preserve efficiency while leaving the underlying angle, proof, offer, or audience objection unexplained.
An Asset Decision
An asset decision asks how to adapt an existing idea. The team might change a hook, visual opening, product treatment, proof point, format, or call to action. This requires angle tracking, otherwise a team can produce many variations without learning what actually changed.
A Messaging Hypothesis
A messaging hypothesis is the strategic layer. It answers questions such as: Which customer objection deserves a new ad? Which competitor pattern should we challenge? Which historical winner has become stale? Which message has not been tested against a specific audience?
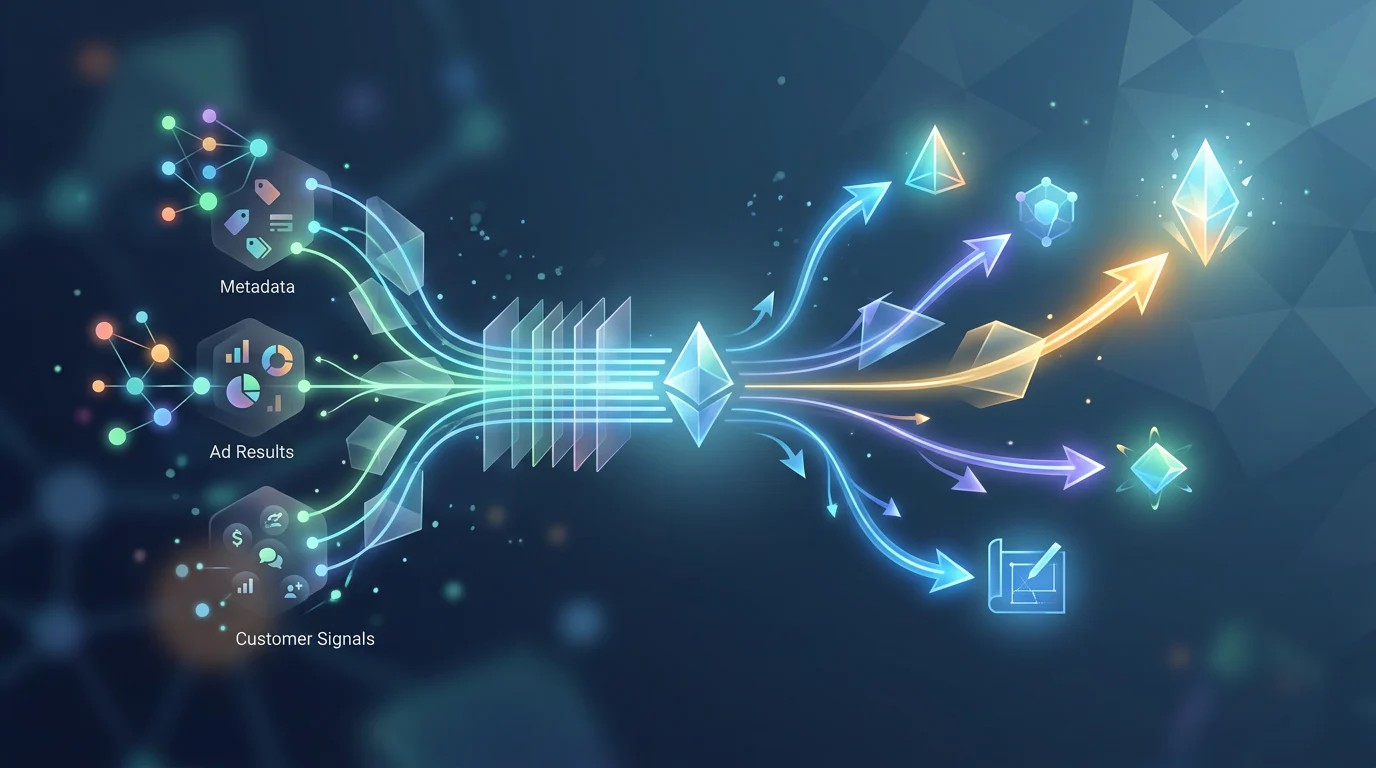
That output should arrive as a ranked test, not a loose pile of insights. We connect performance, customer feedback, competitor movement, and prior outcomes so creative teams know what to test, what to improve, and what to stop repeating.
The Evidence Standard
A useful recommendation needs evidence that a creative strategist can inspect. It should include the underlying performance pattern, relevant market or customer context, the prior test history, the expected learning, and the measurement rule. Without those components, “test this next” is still a guess.
Where Does Each Option Help, and Where Does It Stop?
Each option can solve a real problem. The mistake is asking one tool to perform a job it was not built to do. A campaign platform is strongest at operational scale. A dashboard is strongest at answering questions the team has already defined. We are built for the decision between evidence and the next brief.
| If Your Team Needs To... | Best Starting Point | Why |
|---|---|---|
| Manage many launches, assets, and campaign changes | Campaign platform | Operational workflows reduce repetitive media work |
| Build a ranked weekly test plan | Our platform | We connect multiple creative signals into prioritized hypotheses |
| Report on already-defined metrics | Custom Looker dashboard | A semantic model can support flexible analysis |
| Understand why a fatigue signal matters | Our platform with existing reporting | We translate the signal into a creative decision |
| Create a custom internal data product | Custom Looker dashboard | Technical teams can model their own logic |
A dashboard can detect patterns, but it does not create a recommendation system by default. Looker’s LookML model defines dimensions, calculations, joins, and business rules. Someone still has to decide which classifications matter, how to rank them, and what action should follow.
When creative teams have identified a weak asset or angle, they also need an explicit decision boundary. Our test stop rules help distinguish a weak execution from an angle that has earned deprioritization.
Can a $3,000 Budget Support a Two-Week Launch?
A $3,000 monthly budget is not enough information to publish a fair cost comparison. Neither a campaign platform nor our platform has a universally public price that confirms fit, and Looker’s official model is annual and quote-based rather than self-serve monthly pricing.
A custom dashboard also carries maintenance beyond a software contract. Google documents that Looker projects use Git for version control and deployment, which means model changes require a maintained Git workflow. That work can be worthwhile, but it is not the same as buying a dashboard license.
| Cost And Readiness Factor | Campaign Platform | Our Platform | Custom Looker Dashboard |
|---|---|---|---|
| Publicly Verified Monthly Price | Not publicly listed | Not publicly listed | Not publicly listed |
| Contract Structure | Vendor quote | Vendor quote | Annual commitment |
| Data Preparation | Accounts, assets, rules | Signals, taxonomy, access | Warehouse and semantic model |
| Ongoing Maintenance | Rules, permissions, asset workflows | Decision ownership and signal review | Data engineering and model upkeep |
| Two-Week Viability | Best when already deployed | Confirm onboarding in writing | Only if core data model exists |
The honest choice depends on readiness. If a campaign system is already deployed, use it for operational action. If the urgent need is a ranked next test, ask us to confirm onboarding, access, and scope. Do not commission a net-new dashboard for strategic creative decisions unless your data model and ownership are already in place. Use test prioritization to decide what must be ready before launch.
How Do You Turn Signals into a Weekly Test Plan?
The goal is not to automate every creative decision. It is to create a reliable loop in which the team sees evidence, chooses a test, records the learning, and becomes less likely to repeat an unproductive angle.
Days One Through Three: Access and Taxonomy
Connect advertising performance, creative assets, conversion events, and approved customer-feedback sources. Assign one decision owner, one approver, and a shared taxonomy for formats, hooks, angles, offers, audiences, and test outcomes. Establish creative testing memory before reporting becomes a collection of disconnected results.
Keep customer data governed. Meta explains that its Conversions API sends marketing data to its ad optimization systems, but teams still need clear permission boundaries for every source they use.
Days Four Through Seven: Baseline and Alerts
Set a baseline for performance and fatigue. Decide which signals trigger review, which may trigger an automated media action, and which require a new creative hypothesis. Build one decision view rather than a collection of disconnected dashboards.
A team that stores only results will eventually repeat the same failed angle under a new name. Preserve why the test ran, what changed, and what should influence the next brief.
Days Eight Through Fourteen: Decisions and Learning
Rank three to five test ideas. For each one, record the evidence, owner, asset needed, expected learning, launch timing, success threshold, and stop rule. Review the outcome weekly and update the decision system, not just the report.
A durable creative practice treats each test as accumulated knowledge. Our ad concept framework gives teams a consistent way to compare ideas before production begins.
Why Teams Choose Deepsolv for the Decision Layer
We built Deepsolv for the moment after reporting, when a team still has to decide what to make next. We combine owned ad performance, competitor movement, customer feedback, and remembered test outcomes into a prioritized creative plan for the current week. Our role is not to replace your media buyer, your design team, or your dashboard. It is to give each of them a clearer brief: which angle to test, what evidence supports it, what to avoid repeating, and how success will be judged. That means teams can move from a fatigue alert or a performance decline to an accountable creative decision, without treating every metric change as a reason to produce more variants. If your next meeting ends with “what should we test?”, we can make the answer evidence-backed, owned, and ready to execute. Start with a book a demo
FAQs on Creative Automation Review
Consider the decision first.
Does a Fatigue Alert Tell Us What Creative to Test Next?
Fatigue identifies a performance pattern, not a creative answer. A strategic recommendation connects it to audience context, customer evidence, prior tests, and a ranked experiment.
When Is a Custom Dashboard the Better Choice?
A dashboard works when the team already has clean data, a maintained semantic model, and someone responsible for interpreting alerts. It does not automatically create strategic hypotheses.
Can Every Option Fit a $3,000 Monthly Budget?
No public price confirms that every option fits that budget. Ask for a written quote, implementation timeline, required access, ownership model, and ongoing maintenance responsibilities before committing.
What Data Is Needed to Rank Creative Tests?
Connect advertising performance, creative assets, conversion events, and approved customer-feedback sources. Then establish a taxonomy, a decision owner, alert thresholds, and stop rules before ranking ideas.