AI Creative Test Decision Platform Alternatives for Smarter Test Decisions
Compare AI creative test decision platform alternatives by memory, fatigue signals, and ranked weekly test plans, not generation volume alone.
Creative fatigue is observable, not merely an aesthetic concern. TikTok documents a fatigue threshold above 0.6 when CPA, reach rate, and performance weaken together in its fatigue guidance.
AI creative test decision platform alternatives differ most in what happens after a team has generated an ad. Some systems create more variants or attach a predictive score, while decision-led systems combine account history, fatigue, previous test results, and market context to recommend whether a concept should be tested, stopped, iterated, or scaled.
We built this comparison for in-house creative and performance teams whose bottleneck is selecting the next experiment, not producing another batch of assets.
What Do AI Creative Test Decision Platform Alternatives Actually Do?
Most creative AI starts with a brief, a brand kit, and a request for new assets. That is useful when a team needs more hooks, images, scripts, formats, or placements. It becomes incomplete when the team has a full production queue but cannot explain why one concept deserves the next budget slot over another.
We separate generation, prediction, and decision-making because they answer different questions. A generated asset answers what the team could make. A predictive score estimates what may perform. A decision system should show what to test next, what to stop repeating, and what evidence supports that call. We use Creative test memory to preserve why a previous decision was made, not only which asset was produced.
| Capability | Generation-Focused System | Decision-Focused System |
|---|---|---|
| Main Output | New assets and variations | Ranked test, stop, iterate, or scale action |
| Context Retained | Briefs, prompts, and brand assets | Test history, creative metadata, outcomes, and notes |
| Failure Handling | Produces another variation | Suppresses materially similar failed concepts |
| Evidence | Predicted fit or expected performance | Supporting and conflicting account, fatigue, and market signals |
| Weekly Workflow | Asset production queue | Prioritized experiment plan |
When we review creative systems, we track message, audience, offer, and outcome together so the team can distinguish a reusable angle from a single winning asset. A result without its hypothesis, audience, offer, and outcome cannot reliably prevent a repeat test later.
Which Signals Separate Generation from Decision Intelligence?
A useful decision does not need every available metric. It needs the right evidence for the question at hand. We use account performance to understand what happened, creative metadata to identify what changed, customer feedback to identify the objection or desire behind a result, and market activity to see what themes are visible in the category. We compare those findings with competitor signals without treating public activity as conversion proof.
Public creative activity is useful context, but it has limits. It can show formats, messages, offers, timing, and longevity. It cannot prove another advertiser’s actual revenue, conversion cost, attribution outcome, or incrementality. That distinction protects teams from calling a visible ad a winner when its business outcome remains unknown.
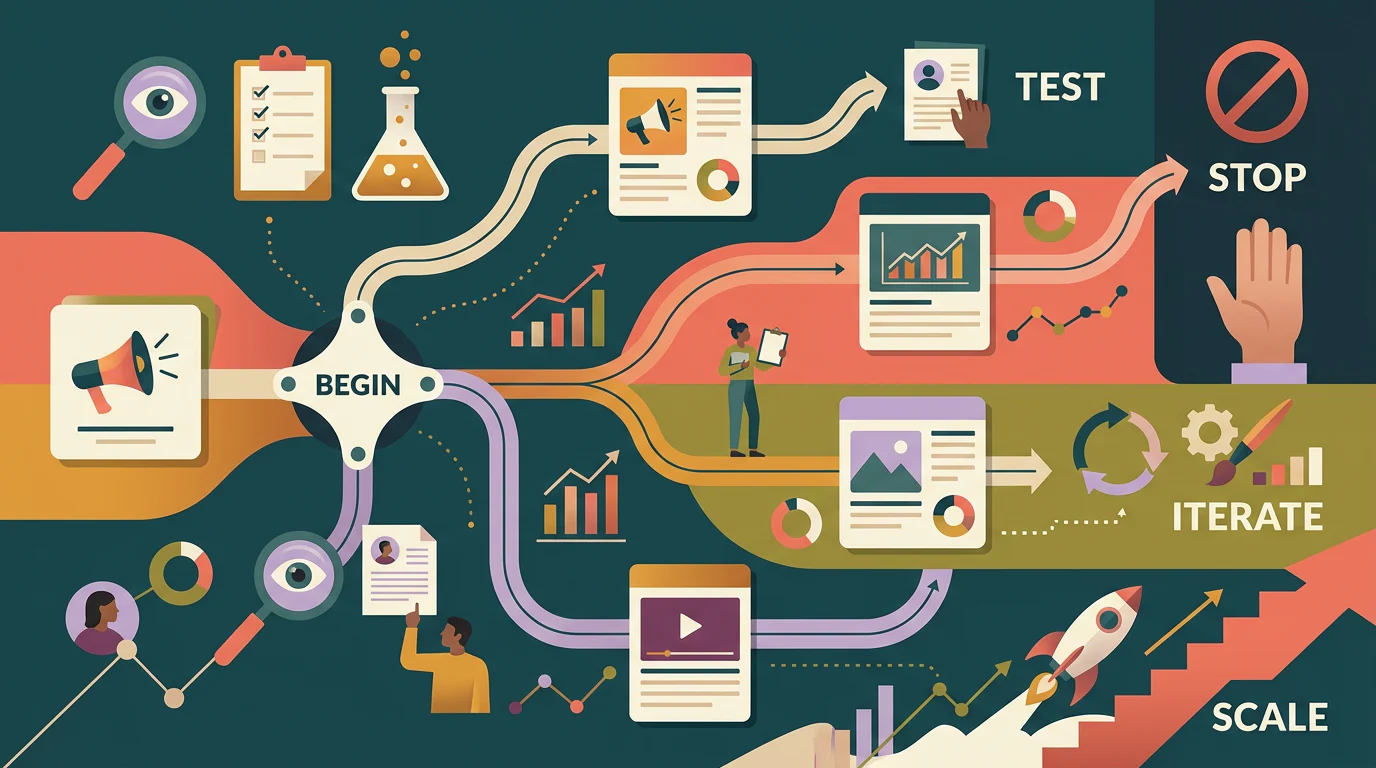
Fatigue deserves its own decision path. A weak proposition may need to stop, while a strong proposition with declining delivery may need a refresh. In platform research involving 8,000 users across six countries, 51% said they preferred brands with varied content, which reinforces the need to distinguish creative repetition from concept failure.
We use fatigue detection alongside performance trends, then examine whether the evidence suggests audience saturation, a tired execution, or an underlying concept that no longer deserves another test.
How Should Teams Decide to Test, Stop, Iterate, or Scale?
A ranked plan needs a visible decision rule. Without one, a predictive score can look authoritative while hiding the assumptions, missing context, and conflicting signals that a strategist needs to challenge.
What Should Move into a Test?
We move a concept into testing when it presents a specific hypothesis, a clear variable, an appropriate control, and a measurable success condition. A fresh customer objection or a new creative pattern can make a concept worth testing, but neither should be presented as a result before the account data exists.
When Should a Team Stop Testing?
We stop a concept when the same hook, format, audience, offer, and objective have already failed under comparable conditions. That is not a permanent ban. A changed product claim, audience, offer, or platform environment can justify reopening the hypothesis, provided the reason is recorded. Our stop rules make those distinctions explicit and preserve the rationale for a future review.
When Does an Idea Deserve Iteration?
We iterate when the underlying concept has evidence of value but a particular execution element is limiting it. The next test should change one meaningful variable, such as the opening, proof point, format, or offer framing, rather than recreate the same ad with cosmetic edits.
What Justifies Scaling?
We scale only when the team can state the observed result, the measurement window, the audience context, and the remaining uncertainty. AI can prioritize the next action, but a model score should remain a hypothesis until tested. The NIST framework supports this approach through its emphasis on measurement, monitoring, documentation, and human oversight.
What Does a Ranked Weekly Test Plan Look Like?
A weekly plan is not a dashboard with a few ideas beside it. It is a decision record that lets a creative lead, media buyer, and analyst agree on what happens next, why it happens, and what should be learned when the test concludes. Our Meta test planning workflow turns that agreement into a controlled experiment rather than a loose creative backlog.
We begin by normalizing the inputs. The plan needs the campaign objective, conversion event, audience, spend context, date range, creative format, angle, and test outcome. Without that context, a past failure can be misread as a universal lesson, or a fatigue pattern can be confused with a permanently weak message.
| Priority | Hypothesis | Supporting Signal | Conflicting Signal | Confidence Basis | Next Action |
|---|---|---|---|---|---|
| 1 | A new proof-led angle may address a recurring customer objection | Recent audience feedback and untested angle | Similar format underperformed previously | New message, comparable audience | Test |
| 2 | A proven angle may need a new opening | Declining delivery with stable conversion intent | Existing creative remains active | Fatigue pattern, not angle failure | Iterate |
| 3 | A familiar format should not re-enter the queue | Two comparable documented failures | New public-market example | Context has not materially changed | Stop |
| 4 | A stable creative may receive more budget | Sustained account performance | Limited evidence outside the current audience | Observed result with known limits | Scale |
The plan should carry forward the learning after each result. We record the hypothesis, the variable, the control, the supporting evidence, the conflicting evidence, the owner, and the next action. TikTok’s API documentation also limits creative-fatigue result queries to the previous 60 days, which is one reason teams should preserve their own durable test records.
Our paid social prioritization framework organizes the weekly queue and keeps the learning attached to the decision instead of leaving it in a disconnected reporting view.
Why Deepsolv Fits a Test-Selection Workflow
At Deepsolv, we built our platform for in-house teams that do not lack ideas, templates, or people who can produce ads. They need a defensible way to decide what enters the next testing cycle and what should not return. We combine authorized performance data, creative context, audience feedback, competitor activity, and past test learnings into a shared decision record. Our weekly plan makes the recommendation, its supporting evidence, the conflicting evidence, and the intended action visible together. That lets strategists challenge a recommendation, retain the learning after a test ends, and avoid confusing a fatigue signal with a permanently weak angle. We do not present public-market activity as another advertiser’s conversion result, and we do not treat a model score as proof. We help teams move from a growing pile of creative options to documented decisions they can test and revisit. Book a Deepsolv demo
FAQs on AI Creative Test Decision Platform Alternatives
These FAQs clarify decisions.
What Is the Difference Between a Score and a Recommendation?
A score estimates likely performance from modeled patterns. A recommendation adds observable account context, prior outcomes, conflicting evidence, and an explicit next action for the team.
Can a Public Ad Record Prove Another Advertiser’s Results?
No. Public ad records show creative, activity, and timing, but they do not reveal another advertiser’s conversion costs, revenue, attribution, incrementality, or underlying business results.
How Should Teams Prevent Repeated Failed Tests?
Suppress a retest when its hook, format, audience, offer, and outcome closely match a documented failure. Reopen it only when a material condition meaningfully changes.
What Belongs in a Weekly Ranked Test Plan?
A useful plan ranks hypotheses, states the control and success criteria, records supporting and conflicting signals, assigns an owner, and ends with one explicit next action.