TL;DR
We help Meta growth teams choose a creative testing tool by finding their blocked workflow stage, not by comparing disconnected feature lists. This guide separates variant creation, controlled testing, live analysis, attribution, fatigue diagnosis, and next-test planning, then shows the controls and evidence labels needed for decisions a team can defend.
Which Meta Creative Testing Tool Fits Your Workflow?
Meta advertising has turned creative review into a data-volume problem, not simply a production problem. A 15-test Meta analysis found a distinct Reels creative treatment produced 34.5% lower cost per result, which is why teams need to separate an observation from a valid test.
The best Meta creative testing tool fits the decision your team cannot make today. We use generation software when a team needs variants, controlled experimentation when it needs a fair element comparison, analytics when it needs to explain live results, and planning when it cannot choose the next test.
We cover the workflow, the evidence each category can produce, the controls a fair comparison needs, and how we turn findings into a defensible next-test queue.
How Does the Meta Creative Testing Workflow Work?
We start with a simple principle: a creative workflow fails at its narrowest point. A team that cannot produce enough variants does not need another attribution model first. A team that can generate hundreds of ads but cannot isolate a hook, offer, or visual change does not have a production problem. It has a test-design problem.
Our working loop has four stages: form a hypothesis, create the minimum useful variants, launch with a declared control, then turn the result into the next hypothesis. The fourth stage matters most because it converts a one-off report into institutional learning. We recommend documenting the intended variable, control, metric, spend guardrail, and decision rule before launch.
We use a fair control to keep the comparison honest. Meta’s published testing guidance advises teams to keep other conditions stable when changing a variable, limit concurrent tests, and allow at least 14 days for sufficient data collection. That does not make every account capable of a formal experiment, but it prevents a team from calling a bundle of changes a hook test. See the Meta testing guidance for the underlying control principle.
Which Meta Creative Testing Tools Match Your Bottleneck?
We do not think a single feature checklist can answer this question. A research workspace, a production suite, a multivariate engine, an analytics dashboard, an attribution layer, and a next-test system can all be useful. They simply improve different decisions.
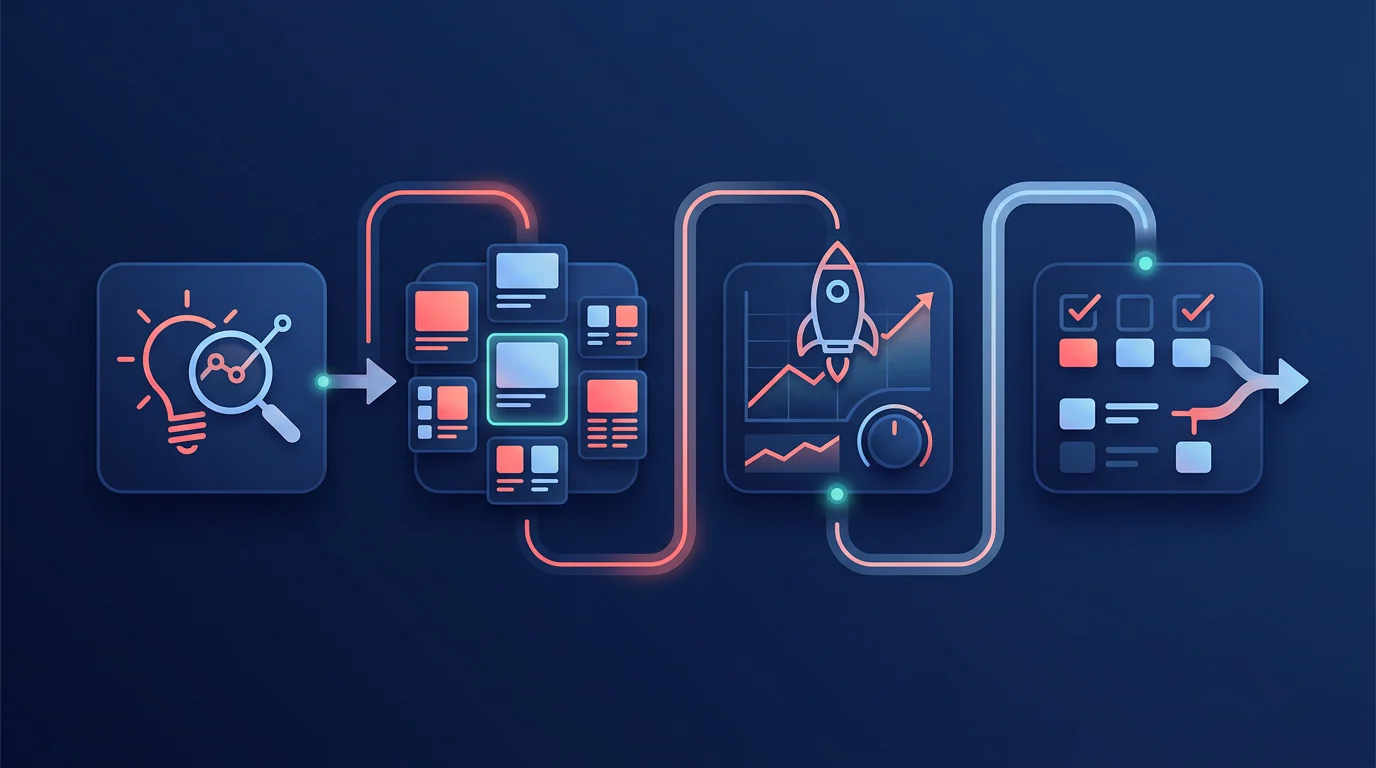
Use this matrix as a sorting mechanism, not a ranking. Meta also recommends starting with one or two variables, a useful reminder that creative complexity should not outrun what a team can actually learn from. The official guidance supports a narrower test before a larger testing program.
| Workflow Layer | Best When The Team Needs | Evidence Produced | What It Does Not Prove |
|---|---|---|---|
| Research and briefing | Better hypotheses, references, and creative direction | Market observations and organized inputs | That an observed external ad will convert for your audience |
| Variant production | More concepts, formats, or edits | Production throughput and asset options | That any variant is a winner before controlled launch |
| Launch and rules execution | Faster publishing, budget guardrails, or operational consistency | Delivery actions and rule outcomes | Why a specific creative element caused performance |
| Multivariate testing | Many static combinations under a defined test design | Comparative outcomes across designed combinations | That results transfer unchanged across audiences or seasons |
| Creative analytics | Faster diagnosis of live creative patterns | Tagged performance correlations and history | That a tag caused the observed result |
| Attribution and measurement | A broader view of revenue and acquisition value | Reported and modeled credit | A randomized creative result |
| Next-test planning | A prioritized, evidence-backed weekly test queue | Linked hypotheses, findings, and recommended actions | That the next hypothesis is already validated |
For high-volume Meta creative testing tools, the useful question is not, “Which platform has the most features?” We ask, “What decision will this improve by next week?” A team that reviews creative by angle can strengthen that answer with angle tracking, because the result stays attached to the concept rather than disappearing into an ad-level export.
Research and Briefing Bottlenecks
When the team is short on ideas, we use research and briefing systems to collect examples, identify messages worth investigating, and turn a promising observation into a production brief. Their value is upstream. They should make the next hypothesis sharper, not claim to validate it.
Launch and Experiment Bottlenecks
When the team has a clear test plan but cannot publish, organize, or protect it consistently, we prioritize launch and automation layers. They can make execution faster and more repeatable. We still need a written control and success condition before automation turns on.
Analysis and Decision Bottlenecks
When hundreds of creatives are live, we use analytics to group results by pattern, format, angle, or timing. That is useful for diagnosis. Our next step is to translate the pattern into a single testable claim, not to mistake correlation for a verdict.
Can You Compare Hooks, Offers, Formats, and Visuals Fairly?
We make a fair creative comparison by changing one declared variable while protecting the surrounding conditions. That is harder than it sounds because a new hook often arrives with a different creator, visual treatment, offer, landing page, audience mix, and delivery pattern. If all of those move together, we learn that the ads differed. We do not learn which element mattered.
We define the test variable in ordinary language: “Does a problem-first opening outperform a product-first opening?” Then we preserve the offer, product, audience strategy, optimization event, placements, landing page, and attribution window as far as the account allows. Our hook test framework helps teams turn that discipline into a repeatable operating rule.
Start with One Variable
We name the changed element before a creative enters production. It can be the hook, visual treatment, offer, proof point, call to action, or format. We do not allow a test label to hide multiple changes, because a vague label makes any later learning unreliable.
Separate Pattern Detection from Causality
Creative analysis can label a video, sort it by visual treatment, and show that certain patterns appeared among high performers. That is valuable evidence for what to test next. It becomes a causal claim only when we deliberately change the element and control the rest of the setup.
Use a Predeclared Decision Rule
We decide what counts as enough evidence before the test starts. That may include a minimum spend level, duration, outcome metric, and stop condition. Without that rule, the team can keep checking results until a preferred creative looks promising, then call the review objective.
A reliable test record should include the hypothesis, control, changed element, live dates, performance context, result label, and next action. That is how we make a creative program cumulative instead of anecdotal. When performance starts to deteriorate, our fatigue response guide helps teams decide whether to adjust the visual, angle, offer, or delivery conditions.
What Does a Meta Connection and Metric Actually Prove?
A Meta integration can mean several things. It may import performance data, retain creative-level history, create campaigns, apply automated rules, or evaluate an experiment. We avoid treating those capabilities as equivalent because a deep connection to delivery data does not automatically provide causal measurement.
| Evidence Label | What We Use It For | What We Avoid Claiming |
|---|---|---|
| Platform-reported metric | Fast review of spend, reach, clicks, and attributed conversions | Incremental business impact |
| Modeled attribution | Broader measurement across channels and customer paths | Controlled proof that one creative element caused lift |
| Predictive score | Prioritizing assets before or during launch | A live experimental result |
| Statistically evaluated experiment | Comparing a defined control and treatment under stated conditions | A universal rule for every account |
We keep these labels visible in our testing workflow. A reported metric can tell us where to investigate. A model can change how we value a result. A controlled experiment can answer a narrower causal question. Confusion starts when a dashboard puts all three beside each other without explaining the difference.
We also preserve the full testing context, including the objective, attribution window, campaign structure, and delivery conditions. That context allows a strategist to distinguish a creative finding from a reporting artifact. Our creative testing framework gives teams a shared record for that review.
Creative fatigue needs the same caution. A rise in frequency, falling click-through rate, or weakening conversion rate can be a useful alert, but it is not proof that the concept is exhausted. We inspect delivery, audience conditions, offer changes, landing-page shifts, and competing activity before deciding whether to refresh, re-angle, or hold.
The strongest operating model is not the one with the most automated alerts. It is the one that helps a strategist explain why an alert matters, what should change next, and what must stay constant for the learning to be useful.
Once that record exists, we can rank the next test by expected learning value rather than by whichever idea was most recently discussed. Our test prioritization method keeps owners, controls, budget guardrails, and decision thresholds attached to every proposed launch.
How Deepsolv Turns Findings into the Next Test
At Deepsolv, we built our workflow for the moment after a team has found a pattern but before it spends again. We connect market research, creative performance, and audience feedback so the weekly conversation ends with a specific hypothesis rather than another dashboard review. Our team view keeps the control, evidence, and reason for each decision together, helping strategists see which ideas have already failed, which signals deserve a follow-up, and which concepts are ready for a measured launch. That makes our role different from a production suite, a reporting layer, or a rules engine. We focus on turning messy paid-social evidence into a test queue your team can defend. Explore how we plan evidence-ranked experiments with the people who make the work, buy the media, and own the commercial result every week, and see our workflow in action, or book a demo
FAQs on Meta Creative Testing Tools
Which Meta Creative Testing Tool Is Best for a Growth Team?
Choose the tool that solves your blocked stage: research, production, controlled testing, analysis, or planning. Decision fit matters more than an exhaustive feature checklist alone.
Can Creative Analytics Prove That a Hook Caused Conversion Lift?
Not alone. Tags reveal patterns across ads, but causal claims require one deliberate variable change, stable conditions, sufficient exposure, and a predeclared decision rule beforehand.
Is Modeled Attribution the Same as a Creative Experiment?
Use reported metrics for operational signals, modeled attribution for broader measurement, and controlled experiments for causal claims. Keep those evidence labels visible during every creative review.
How Should a Team Test with Limited Volume?
Start with one control, one hypothesis, a defined metric, and a stop rule. With limited volume, test fewer variables and preserve learning for later launches.
What Makes a Next-Test Recommendation Useful?
Useful recommendations name the hypothesis, control, changed element, owner, budget guardrail, and decision threshold. Without them, an observation merely sounds like an action to readers.