TL;DR
At Deepsolv, we build reliable Meta creative tests by turning competitive observations and first-party results into falsifiable, ranked hypotheses. We explain how to isolate variables, choose a test method, validate delivery and tracking, interpret uncertainty, and keep a learning ledger that improves the next weekly plan.
Creative testing looks simple until delivery, attribution, and production pressure make every result feel debatable. A large test study of 181,890 Meta A/B tests found that delivery can differ meaningfully between test cells, complicating a simple “creative A beat creative B” conclusion.
A Meta Ad Creative Testing Framework produces reliable learnings when you define a falsifiable hypothesis, control, primary metric, delivery requirements, and decision rule before launch. Use competitive ads to generate hypotheses, use your own results to validate them, and let AI rank evidence and gaps, never promise a winner before spend.
We use this framework to turn an overfull concept queue into a weekly decision system. It covers the seven steps: define the question, gather evidence, form a hypothesis, score the backlog, choose a method, validate the readout, and record the next learning.
How Does a Meta Ad Creative Testing Framework Produce Reliable Learnings?
Reliable learning starts before an ad enters review. A team needs one question, one defined control, and one decision it will make from the result. When several changes arrive together, such as a new angle, new creator, new offer, and new landing page, the result may be commercially useful but it does not explain which change mattered.
Meta’s delivery system also shapes the outcome. Meta says ad sets enter learning after creation or significant changes, and its current learning guidance explains that delivery explores audiences, placements, and opportunities while pursuing the selected optimization event. That is why we treat delivery conditions as part of the test record, not background noise.
| Test Method | Best Question | Useful Decision | Important Limitation |
|---|---|---|---|
| Platform Experiment | Which configured option performs better? | Select a version for this account setup | Delivery can still influence audience composition |
| Lift Test | Did advertising create incremental outcomes? | Assess campaign incrementality | Does not isolate a single creative mechanism |
| Isolated Ad Sets | Is this variable worth deeper investigation? | Make a directional creative decision | Uneven delivery can weaken causal claims |
| Sequential Test | Does the result recur over time? | Decide whether to replicate or scale | Seasonality and auction conditions can change |
| In-Campaign Read | Is the asset viable and functioning? | Triage technical or early delivery issues | Does not establish a winner |
The goal is not perfect laboratory control. The goal is an auditable decision that states what changed, what stayed fixed, what Meta delivered, and what the team learned. Our test planning guide expands on how to translate that record into a practical weekly queue.
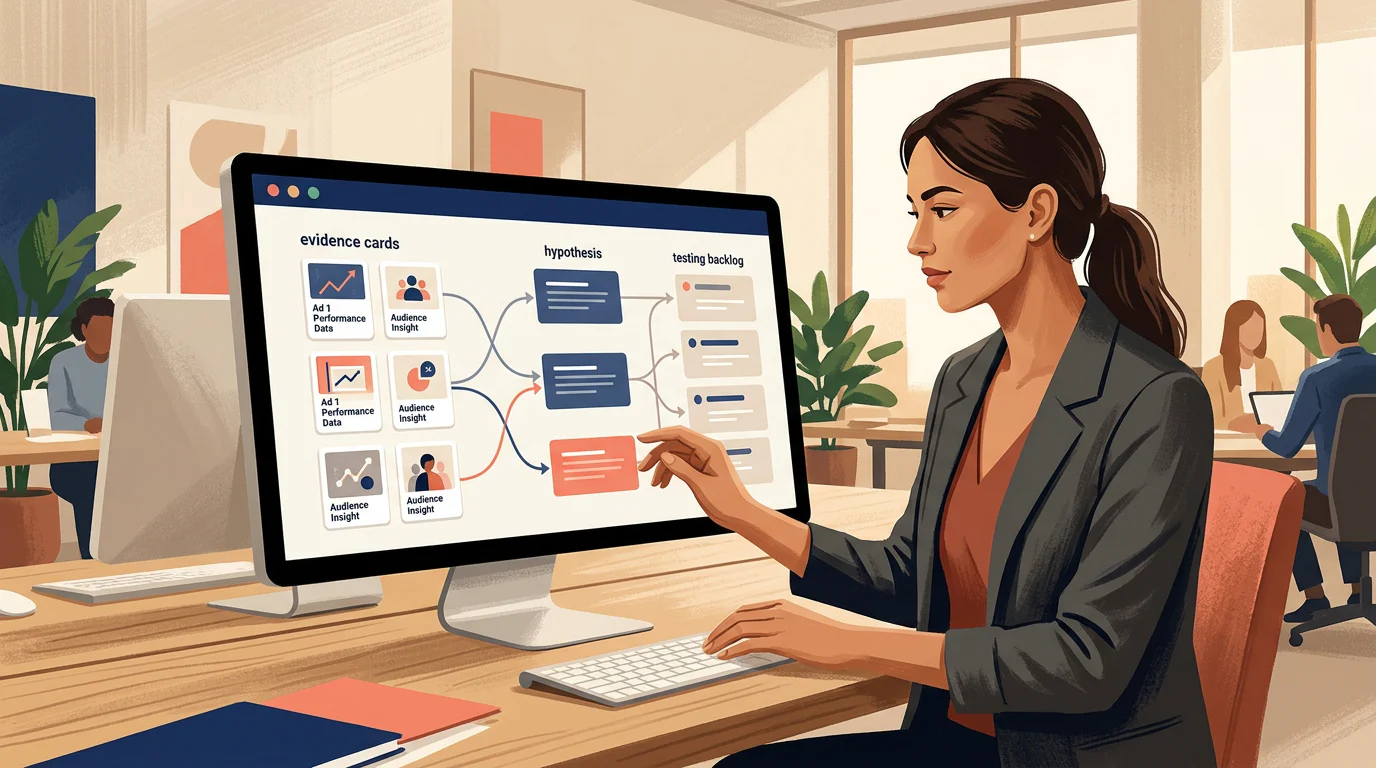
How Do You Turn Evidence into a Testable Hypothesis?
Competitive research is valuable because it exposes visible market patterns. It can show that an angle, hook, format, or offer appears repeatedly. It cannot tell us another advertiser’s conversion quality, audience mix, profit margin, attribution model, or incremental sales. We use market evidence to ask better questions, then use first-party results to answer them.
Meta’s public Ad Library lets researchers inspect active creative and says ads generally appear within 24 hours of receiving their first impression. That visibility makes it useful for observation, but visible activity is not proof of account-level success. Our competitive research workflow keeps the source, observation date, market, and proposed test together so a pattern never becomes a false performance claim.
| Evidence Input | What It Can Suggest | What It Cannot Prove | What We Record |
|---|---|---|---|
| Competitive Creative | Repeated angles, offers, hooks, and formats | Profitability or conversion performance | Source, date, market, pattern |
| First-Party Results | Account-specific response and repeatability | Universal transferability | Test ID, control, metric, result |
| Customer Feedback | Objections, desired outcomes, language | Scalable paid performance | Theme, volume, supporting examples |
| AI-Assisted Analysis | Redundancy, evidence gaps, and backlog order | A guaranteed winner | Inputs, rationale, confidence note |
A useful hypothesis card makes the idea falsifiable before production begins. It should name the audience, angle, hook, format, proposed mechanism, expected outcome, control, primary metric, and condition that would disprove the claim. For example, “For returning site visitors, a problem-first hook in creator video will improve qualified purchase efficiency versus the current benefit-first control because it resolves a known objection.” The falsification condition is equally important: the expected improvement does not appear after a valid comparison.
Our comment analysis process is useful here because it separates a visible creative motif from the customer objection or motivation that could make it relevant.
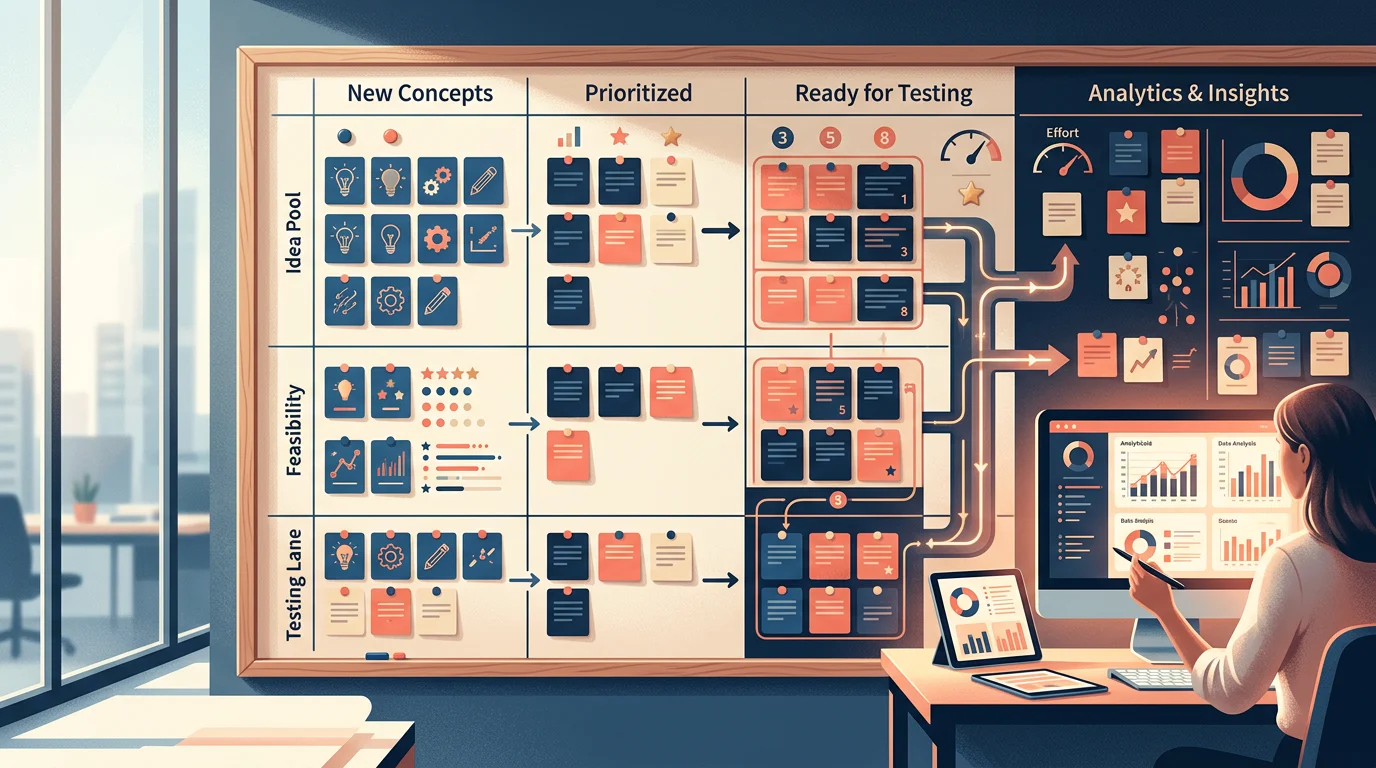
How Should You Rank the Backlog and Choose a Test Method?
A DTC team spending meaningfully on Meta can still waste budget if forty concepts receive equal attention. The best backlog is not a pile of attractive ads. It is an ordered set of learning opportunities, where each concept earns a place because it could change the next production or media decision.
We rank concepts before they become assets. This prevents the familiar failure mode where the loudest stakeholder, newest swipe, or easiest asset wins simply because it is ready first.
Score Concepts by Decision Value
We score evidence strength, expected impact, novelty, production effort, learning value, and redundancy. The score is not an oracle. It is a forcing function that makes tradeoffs visible and makes it easier to explain why a smaller, faster test should beat a more polished but repetitive concept.
| Criterion | Higher Score Means | Common Warning Sign |
|---|---|---|
| Evidence Strength | Multiple relevant first-party or customer signals support it | One visible market example carries the idea |
| Expected Impact | The result could affect a material business decision | The upside is vague or cosmetic |
| Novelty | It tests a meaningfully different angle or mechanism | It repeats a live concept with minor edits |
| Production Effort | The asset can be made without blocking stronger work | Complexity exceeds likely learning value |
| Learning Value | Either outcome changes the next decision | A win or loss would change nothing |
| Redundancy | It fills a knowledge gap in the backlog | The same question is already in flight |
AI-powered Facebook ad test planning works best at this stage. We use it to cluster similar ideas, retrieve related outcomes, flag missing variables, and suggest an evidence-backed order. It should never claim to know tomorrow’s winner. The auction, audience response, delivery optimization, and measurement environment still decide that after launch.
Separate a New Angle from a New Execution
An angle is the underlying promise or framing, such as solving a recurring problem, demonstrating a mechanism, or addressing a purchase objection. An execution is how that angle appears, such as a static image, creator video, comparison, or testimonial. Testing both at once may be commercially efficient, but it weakens the explanation.
Our angle tracking method helps teams keep that distinction intact. It lets us ask whether the angle is exhausted, whether the hook is weak, or whether the format simply failed to earn attention.
Match the Method to the Learning Question
Use a platform experiment when the question requires a structured comparison between configured options. Use isolated ad sets when the goal is directional learning under controlled conditions. Use sequential testing when a high-stakes result needs replication. Use an in-campaign read to diagnose technical viability, not to declare a permanent winner.
Research on platform measurement shows why this distinction matters: delivery optimization nonrandomly selects people predicted to take the desired action, making observational comparisons difficult to correct afterward. Method choice should be a required backlog field, not an afterthought.
How Do You Lock the Test and Read Delivery Without Fooling Yourself?
Before launch, we lock the primary metric, attribution setting, audience definition, placements, optimization event, budget, duration, and decision criteria. The exact requirements should match the account’s economics and expected conversion volume. A fixed generic spending rule is less useful than a threshold the team can explain before results arrive.
Good experimental practice requires a control, a variation, an expected effect, and a plan for sufficient observations. Public A/B guidance similarly recommends deciding the sample, duration, and outcome before analyzing the result. On Meta, those choices also need to survive the platform’s learning behavior and auction dynamics.
Lock the Conditions That Affect Delivery
Hold the audience, optimization goal, bid strategy, attribution setting, placements, and control as stable as possible when the learning objective is creative-specific. If those elements change, record the change and downgrade the confidence of any creative conclusion.
A field experiment study describes Meta A/B tests that used balanced groups and equal daily budgets. That is the standard to aim toward when the question is comparative performance, while recognizing that real delivery still responds to the platform’s optimization system.
Run Quality Checks Before Calling a Loser
Before we call a creative a loser, we confirm that it was approved without warnings, rendered correctly in planned placements, reached the intended destination, and received comparable delivery. We reconcile platform events with the order system, record pauses or edits, and check attribution settings by test cell.
If approval, rendering, tracking, destination, or a material edit fails, the result is operationally invalid, not a creative loss. The right next action is to fix the defect and relaunch the test, not to contaminate the learning ledger with a false conclusion.
Classify the Outcome with a Decision Tree
A valid result that meets the predeclared decision criteria becomes a winner. A valid result that misses those criteria becomes a loser. A valid comparison with insufficient evidence becomes inconclusive. A test compromised by tracking, rejection, technical defects, or major edits becomes invalid.
Our testing stop rules prevent premature calls when an ad has not delivered fairly or when the account has not collected the evidence needed for the original question.
How Do You Turn Results into Next Week’s Learning System?
The point of a readout is not a report card. It is a better next hypothesis. A winner should tell us what to replicate, a loser should tell us which proposition lost support, an inconclusive test should identify the uncertainty, and an invalid test should expose the operating failure.
We use a learning ledger that records the test ID, date, control, changed variable, evidence source, delivery conditions, primary metric, result class, failure reason, confidence note, and next hypothesis. Our testing memory keeps those records available when similar ideas return months later.
| Result Class | What It Means | Next Action |
|---|---|---|
| Winner | Valid test supports the predeclared decision | Replicate, adapt, or scale with guardrails |
| Loser | Valid test does not support the hypothesis | Preserve the learning and test a distinct mechanism |
| Inconclusive | Valid setup, but evidence does not decide | Extend, simplify, or redesign the comparison |
| Invalid | Technical or measurement failure compromised the test | Correct the failure and relaunch |
This is how we stop scrambling after two strong weeks and a sudden decline. Instead of treating every performance swing as proof that an angle died, we compare the current result with the control, delivery conditions, tracking quality, and prior angle history. The backlog then becomes a compounding asset rather than a rotating collection of ad files.
Build Your Weekly Meta Test Plan with Deepsolv
At Deepsolv, we help paid-social teams replace scattered swipe files and fragile spreadsheets with a weekly decision system. We connect the signals that matter: recurring market messages, your own creative performance, customer feedback, test outcomes, and the production effort behind each concept. Our role is not to claim that an algorithm can see tomorrow’s winner. We help your team see why a concept deserves a test, what must stay controlled, and what the result should change next. That gives creators, analysts, and media buyers one shared backlog instead of competing opinions. If your team has more ideas than clean learning capacity, we can help turn the backlog into a repeatable operating rhythm, from evidence collection through readout and memory. We make the handoff between creative research and accountable media decisions practical, visible, and repeatable each week. Build your next more defensible weekly test plan with Deepsolv.
FAQs on Meta Ad Creative Testing Framework
These questions address the limits of prediction and the operating choices that make creative testing dependable. They are the rules we use to keep a weekly test plan grounded in evidence.
Can AI Predict Which Meta Creative Will Win Before Spend?
No. AI can organize observations, prior results, production constraints, and uncertainty into a ranked plan, but live auction delivery and account signals determine actual performance.
Why Did Meta Give One Creative More Delivery?
Meta optimizes delivery toward predicted outcomes, so variants can reach different users, placements, and auctions. Treat uneven spend as diagnostic context, not proof a concept lost.
Can Competitive Research Prove an Angle Will Work?
Competitive research reveals visible messages, formats, and recurring offers. It cannot reveal conversion quality, margins, targeting, attribution, or incrementality, so it should only generate hypotheses.
When Is a Meta Test Invalid Instead of Inconclusive?
Call a test invalid when approval, rendering, tracking, destination, attribution, or edits undermine comparison. Call it inconclusive when valid setup does not produce enough evidence.
What Should a Creative Testing Ledger Record?
Record the control, changed variable, evidence source, delivery conditions, decision metric, outcome class, failure reason, and next hypothesis in test prioritization. Each launch becomes reusable operating knowledge.